Disaggregated inference: when to split prefill and decode
AWS added NVIDIA Dynamo as a managed HyperPod Inference runtime. The useful decision is not whether to adopt the release, but whether representative traffic proves that separating prompt processing from generation removes a real bottleneck without moving it into the network, KV cache, or operations.
- Published
- min read
- 6 min read
- Categoría
- AI Systems
On this page
6 chapters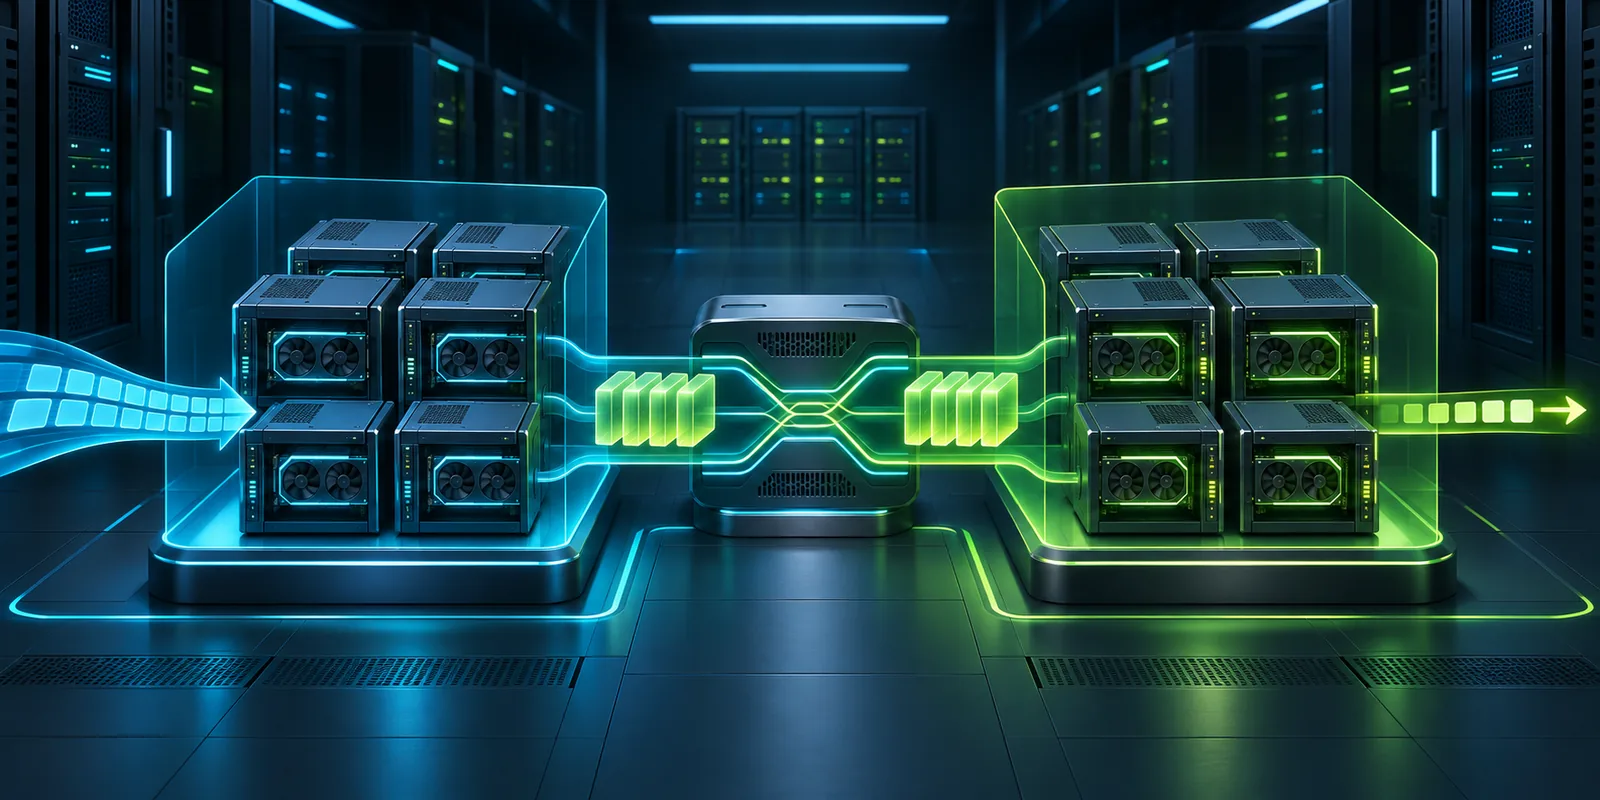
Chapter 01
When does splitting prefill and decode pay off?
Disaggregated inference pays off when prompt processing and token generation contend persistently, can be sized independently, and the cost of transferring KV cache is lower than the contention it removes.
On November 19, 2026, three America/Lima calendar days before this article, AWS published its inference technical review and highlighted managed NVIDIA Dynamo on SageMaker HyperPod Inference. The v3.8 release that enables the runtime is dated November 18. The mechanism separates prefill, which processes the prompt and builds KV cache, from decode, which generates tokens autoregressively. Each pool can use a different GPU count, parallelism strategy, and hardware profile; a router coordinates the request and transfers cache to the worker that continues generation. The split pays off when long prompts block active token generation, the two phases need different capacity, and a representative test proves that handoff costs less than the contention removed. When those three conditions do not hold together, aggregated serving retains a simpler and more efficient operational path.
That separation is not a universal improvement. At low concurrency, an aggregated worker avoids transfer, coordination, and capacity fragmentation. Disaggregation becomes valuable when long or irregular prompts block generation, when prefill and decode need different resources, or when a model spans machines. The decision must start with an observable queue and service objective: time to first token, inter-token latency, accepted throughput, errors, and cost per completed request. If the team cannot attribute the bottleneck to one phase, it does not yet have evidence for adding another topology.
Chapter 02
What actually changes in a request path
In an aggregated topology, the same worker receives input tokens, runs prefill, retains KV cache, and performs decode. It is simple, keeps cache local, and is often efficient while both phases fit a stable operating profile. In a disaggregated topology, the frontend selects a prefill worker, which produces cache and returns handoff metadata; the router then chooses a decode worker, moves or references the required blocks, and streams the response. Independence lets each pool scale for its own pressure, but it introduces a distributed boundary into every request.
Dynamo also provides KV-cache-aware routing. Instead of balancing only by request count, it can consider prefix overlap and load to avoid recomputing context. Its documentation also warns that decode should not chase prefix reuse after remote prefill as though transferred blocks were magically deduplicated. Topology and engine need one shared truth about where cache lives, how it moves, and when it becomes invalid. A cache hit-rate metric alone does not prove value if transfer increases queueing or reduces memory available for active sequences.
| Decision | Aggregated | Disaggregated |
|---|---|---|
| Path | One worker runs both phases | Separate pools with a handoff |
| Scaling | One combined capacity | Independent prefill and decode |
| KV cache | Local to the worker | Must be transferred or shared |
| Primary risk | Cross-phase contention | Network, routing, and fragmented capacity |
Chapter 03
Six signals before changing the topology
First, input distribution: measure prompt length, prefix reuse, and bursts, not just the average. Second, output distribution: decode scales with concurrency, generated tokens, and active memory. Third, contention: prove that long prefill raises inter-token latency or blocks generation for other requests. Fourth, cache locality: record useful hits, evictions, and bytes transferred per request. Fifth, network and placement: verify the intended transport between nodes and ensure affinity does not turn a rack or zone failure into a cascade. Sixth, accepted economics: calculate cost per request that meets every SLO, not theoretical tokens per GPU.
AWS's published benchmark illustrates why workload shape matters. For Qwen3-235B-A22B-FP8 with TensorRT-LLM on two p5en.48xlarge instances, 4,000-token inputs, and 200-token outputs, AWS retained points meeting sub-one-second P90 time to first token and at least 50 tokens per second per user. In that experiment, the best disaggregated configuration reached 207 output tokens per second per GPU versus 101 for aggregated serving. That is a result for this combination, not a multiplier transferable to another model, network, engine, or traffic distribution.
Chapter 04
How do you design an experiment that can decide?
Start with representative, anonymized traffic replay or a documented synthetic distribution. This example is hypothetical: a technical assistant receives 6,000-token base prompts, retrieves between zero and 20,000 tokens, and generates answers from 100 to 1,200 tokens. Build a matrix across input length, output length, concurrency, and prefix reuse. For every cell, compare the current aggregated setup with several prefill-to-decode ratios while holding model, precision, engine, batching limits, and acceptance criteria constant. Warm cache explicitly and separate cold, warm, and post-eviction results.
Promote only points that simultaneously meet P50/P95/P99 TTFT, inter-token latency, throughput, error rate, and memory-safety targets. Then add cost: GPU-seconds, network, cache storage, and idle capacity. Finally test degradation: loss of a prefill worker, saturated decode, a broad cache miss, slow handoff, partial rollout, and router restart. Dynamo documentation notes that route activation can return HTTP 503 rather than send a request to an incompatible decode worker; clients need budgeted retries with jitter, not unlimited duplicate work.
Chapter 05
The risks a happy-path benchmark does not show
Disaggregation reserves GPUs for pools with different profiles. If decode is constrained by KV-cache capacity, moving GPUs into prefill can reduce total concurrency even while improving TTFT. When traffic falls, two small pools may be less utilized than one shared pool. If the network misses its expected bandwidth and latency, handoff replaces compute contention with distributed waiting. And if routing, autoscaling, and metrics do not share model, version, and tenant labels, an aggregate improvement can hide regressions in the queue the business actually pays for.
Managed does not mean responsibility-free. HyperPod installs and upgrades components, manages capacity, and recovers nodes, while Dynamo decides sharding, phase separation, and routing. The team still owns recipes, limits, ratios, rollout policy, and rollback signals. Keep a validated aggregated path for workloads that do not benefit, define version compatibility, and do not change topology and engine at the same time. The rollback boundary must cover configuration, cache, router, and client; rolling back only the model can leave requests on an incoherent path.
Chapter 06
The decision: remove contention, do not buy a topology
Keep aggregated serving when the workload is small or stable, local cache works, there is no measurable cross-phase interference, and operational headroom matters more than theoretical optimization. Test disaggregation when long prompts block decode, input and output profiles diverge, pools need independent scaling, or a model must span nodes. Adopt it only when the gain holds across multiple periods, survives failures, and lowers cost per accepted request after network and idle capacity are counted.
The AWS release reduces platform work, but it does not replace the experiment. Turn the six signals into a promotion contract: input distribution, output distribution, contention, cache locality, transport, and accepted economics. When each has a metric, threshold, and owner, topology can evolve without turning production into a laboratory. If you are designing an inference path for a real product, Wasyra can help build the representative benchmark, observability, and bounded rollout before architecture and spending become commitments.
Written by
Wasyra Lab
AI systems and operations architecture
Wasyra Lab publishes practical frameworks for designing AI agents, automations, and operating flows that survive production.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
AI Systems
Agent hooks: 7 tests before tools execute
AgentCore's new lifecycle hooks expose four control boundaries. This guide turns them into seven tests for authorization, failure, and auditability.
ArticleAI Systems
Scientific post-training: 7 evidence gates
Nemotron for Science opens scientific post-training. These seven gates prevent proxy optimization, test leakage, and false improvements.
ArticleKeep reading
Keep reading
AI Systems
Agent hooks: 7 tests before tools execute
AgentCore's new lifecycle hooks expose four control boundaries. This guide turns them into seven tests for authorization, failure, and auditability.
ArticleAI Systems
Scientific post-training: 7 evidence gates
Nemotron for Science opens scientific post-training. These seven gates prevent proxy optimization, test leakage, and false improvements.
ArticleAI Systems
Agentic RL: how to read MLPerf Training 6.1
MLPerf now measures agent post-training. Learn how to read time to quality, workload limits, and useful infrastructure decision signals.
Article