ReplaySSM: how to evaluate hybrid inference
ReplaySSM reframes recurrent state in hybrid models as a checkpoint plus a bounded buffer of recent inputs. This guide translates the paper, code, and integrations into six decisions for validating memory traffic, speculative rollback, precision, concurrency, compatibility, and end-to-end outcomes before adopting the mechanism.
- Published
- min read
- 6 min read
- Categoría
- AI Systems
On this page
7 chapters- 01When can ReplaySSM improve hybrid inference?
- 02What does the checkpoint-buffer split change?
- 03Six decisions before adopting ReplaySSM
- 04Hypothetical example: a long-context support assistant
- 05How do you evaluate speed without losing quality?
- 06Limits: compatibility, operations, and change cost
- 07The decision: profile before rewriting state
Chapter 01
When can ReplaySSM improve hybrid inference?
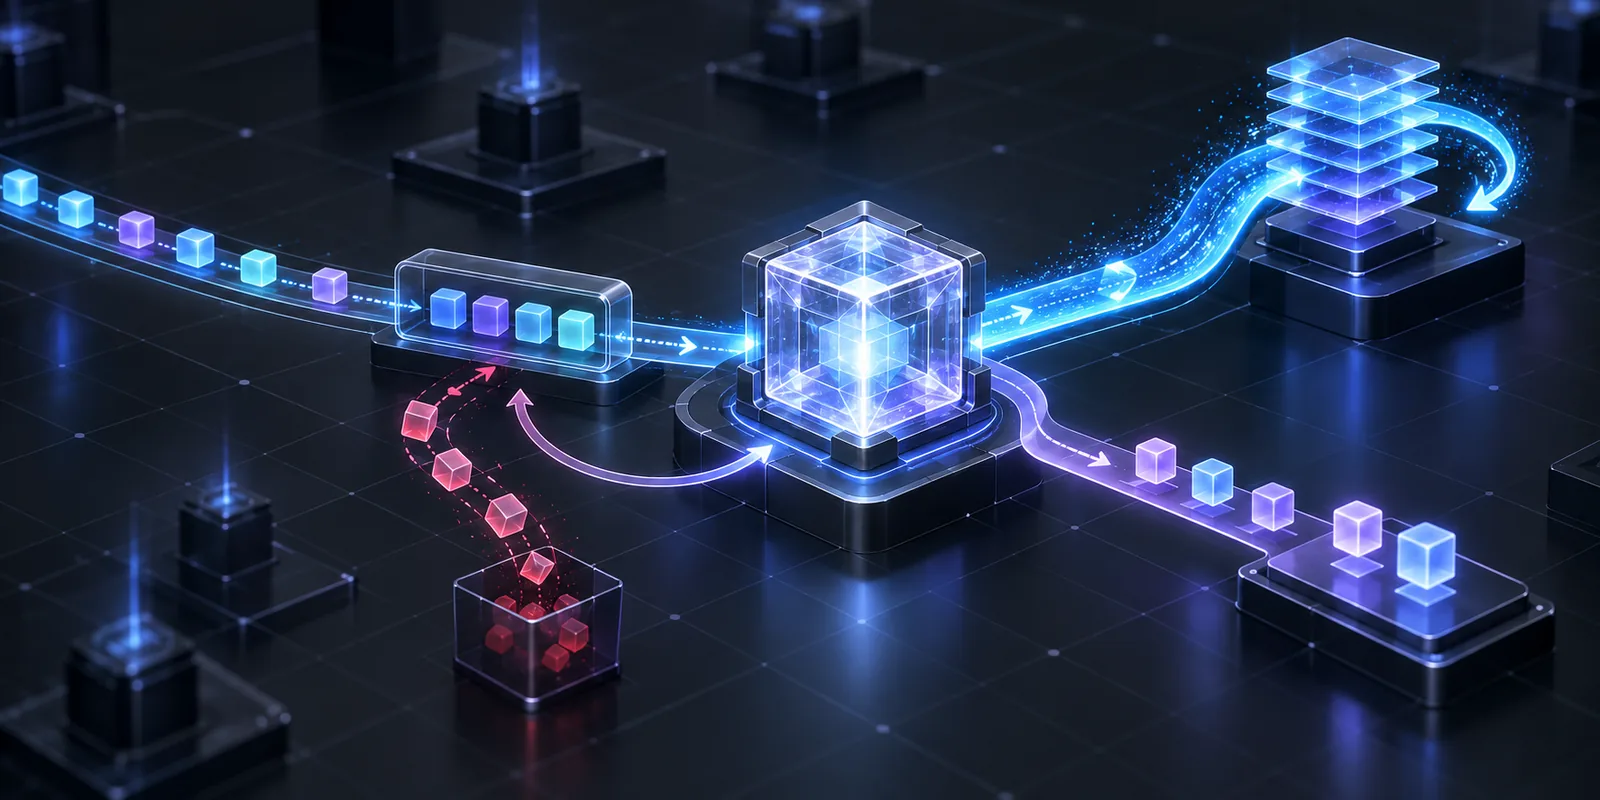
ReplaySSM can improve inference when a hybrid model combines many recurrent SSM layers with a few attention layers and serving runs at enough concurrency for state movement, rather than arithmetic, to become the bottleneck. The mechanism represents that state as a checkpoint plus a bounded buffer of recent inputs. Each token can produce an output by reading the checkpoint and buffer, while the large write happens only when the buffer flushes. This separation also makes speculative-token rollback a pointer move and allows a low-precision read copy without feeding its error into future recurrent updates. It is not a universal speedup: the paper observed no gain at batch size one, its figures cover four models on H100 or B300 GPUs under specific configurations, and several paths are not yet upstream. A sound decision requires profiling your model, sequence length, batch, speculative acceptance, precision, and end-to-end outcome before replacing the serving path.
NVIDIA published its technical explanation on October 12, 2026, one Lima calendar day before this article. The original paper had been submitted to arXiv on October 9 at 15:59:40 UTC. That distinction matters: the fresh editorial event is yesterday's explanation and integration update; the measurements belong to the authors' work and were not reproduced by Wasyra.
Chapter 02
What does the checkpoint-buffer split change?
In a conventional SSM layer, recurrent state performs two jobs at every step: it is read to compute the token output and updated for the next step. Reading and writing a large matrix with little arithmetic can make the kernel memory-bandwidth-bound. ReplaySSM unrolls the recurrence over a short window. It keeps an earlier checkpoint and stores only recent input vectors; ordinary steps compute output from both pieces, and a full window is folded into a new checkpoint. The idea does not remove state or make it free: it reduces the frequency of large writes while adding computation and metadata around the buffer.
The same representation changes speculative rollback. A conventional decoder may need a state snapshot after each proposed token because an updated recurrence has no cheap inverse. ReplaySSM appends proposed inputs to the buffer, verifies the block, and advances a pointer to the last accepted token; later entries are ignored. This resembles KV-cache rollback, but it helps only when draft acceptance and concurrency offset the cost of the drafter, verification, and flushes.
It also decouples read precision from recurrence precision. A compact copy can serve frequent reads while a higher-precision checkpoint feeds future updates. Rounding error in the compact copy affects the current output but is not recirculated indefinitely. This is a useful architectural property, not a replacement for quality tests across sequence length, domain, and prompt distribution.
Chapter 03
Six decisions before adopting ReplaySSM
Treat ReplaySSM as a systems change, not a performance flag. These six decisions need an answer and evidence before rollout. If one fails, a kernel benchmark can improve while service latency, memory, quality, or maintainability gets worse.
| Decision | Question | Evidence |
|---|---|---|
| 1. Bottleneck | Does SSM state dominate traffic or latency? | Profile by layer, batch, and sequence length. |
| 2. Window | Which buffer length balances flushes and computation? | Window sweep with p50 and p99. |
| 3. Speculation | How many draft tokens are actually accepted? | Acceptance, rollback, throughput, and memory. |
| 4. Precision | Which copy can be compressed without harming tasks? | KL, accuracy, and quality by length. |
| 5. Integration | Is the required path merged and supported? | Version, PR, fallback, and correctness tests. |
| 6. Outcome | Does the complete request improve under its SLO? | TTFT, TPOT, p99, cost, and accepted quality. |
Chapter 04
Hypothetical example: a long-context support assistant
Imagine a SaaS platform serving a hybrid model to summarize support histories and propose a reply. During business hours it batches requests and reaches high concurrency; overnight it receives a few interactive sessions. Some replies use long context, but most finish quickly. The team sees a striking throughput improvement in a benchmark and considers enabling ReplaySSM for all traffic.
The right test separates cohorts. It first profiles how much decode time belongs to SSM layers at batch sizes 1, 16, 64, and the sustainable maximum. It then compares standard and speculative decoding using the actual length and acceptance distributions. Three precision variants are run, and replies are graded against product rules: facts supported by the ticket, no invented actions, useful formatting, and consistency in long conversations. Cancellation and rebalancing are also simulated to ensure buffers do not leave orphaned state.
The hypothetical rollout may find that the path benefits the daytime processing pool but not overnight batch-one sessions. Traffic is then routed by workload class while the earlier kernel remains available as a fallback. This example is not a Wasyra customer or result; it shows why an architecture with conditional benefits needs segmentation rather than global enablement.
Chapter 05
How do you evaluate speed without losing quality?
Use a representative traffic replay with warmup, the same model version, and equal memory limits. Record time to first token, time per output token, throughput, p50/p95/p99, memory per sequence, effective batch size, and flush frequency and cost. For speculation, add draft length, acceptance rate and length, avoided snapshot bytes, and requests evicted under memory pressure. Compare by prompt and generation length; one average will hide where the bottleneck changes.
The published figures should shape the experiment, not predetermine its result. At batch size 256, the authors report 1.20x to 1.47x end-to-end decode speedups across four models; for two 120B-class models at batch size 512, they report 1.85x and 2.10x speculative throughput relative to the compared speculative implementation. They also state that batch size one showed no speedup. Reproduce your own operating point and publish intervals or enough repetition to distinguish a stable gain from scheduler, thermal, or cache noise.
For precision, do not stop at average divergence. Build buckets by length and task, compare logits or KL when possible, and measure the criterion the product accepts. The paper shows that separating read and recurrence precision limits error accumulation, yet one of four evaluated configurations fell outside roughly two points of the FP32 baseline on GPQA-Diamond. Set the allowed margin before seeing the result and retain long adversarial tests.
Chapter 06
Limits: compatibility, operations, and change cost
ReplaySSM requires a recurrence that can be unrolled in the form implemented by the kernel. The authors' repository covers Mamba2 and Gated DeltaNet; that does not make every linear, recurrent, or hybrid model compatible. Verify state layout, head grouping, supported precision, draft head, and checkpoint differences. A nominal architecture match does not replace token-by-token numerical tests.
Integration maturity is also mixed. The README distinguishes merged paths, open pull requests, and implementations available only in the research fork. Maintain an explicit matrix by engine, version, model, and mode; pin reproducible commits and rehearse software rollback, not just token rollback. If an engine update changes the interface or kernel, the service must safely return to the known path.
Finally, throughput is not useful capacity if queues, variance, or errors increase. A per-sequence buffer consumes memory; flushes create periodic work; cohort routing adds complexity; and maintaining a fork has a cost. Include operations, observability, upgrades, and fallback in the economic case. The optimization is valuable when it improves SLO per dollar or watt inside the quality margin, not when it wins one isolated number.
Chapter 07
The decision: profile before rewriting state
ReplaySSM offers a transferable idea: when one state serves different functions, separating them can unlock optimizations that a monolithic representation prevents. The checkpoint preserves continuity; the buffer makes recent work reversible; different-precision copies separate speed from error accumulation. The mechanism deserves a test when profiling confirms that recurrent-state traffic dominates and the workload has enough concurrency.
Start with a reversible slice: one model, one supported GPU, one traffic distribution, and one SLO. Answer the six decisions, preserve the earlier path, and expand only if the complete request improves without crossing the quality margin. Wasyra can help design and implement custom AI systems, but the first deliverable should be a reproducible profile and rollout gate, not a promise based on the paper's best chart.
Written by
Wasyra AI Systems
Trust, copilots, and enterprise adoption
Wasyra AI Systems covers guardrails, suggestion-first modes, and review design so work assistants earn real adoption.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
AI Systems
GPU clusters: how to allocate capacity without priority inflation
Time budgets, fair-share, and execution contracts turn a contested GPU queue into a verifiable operating decision.
ArticleAI Systems
AI agents: how to contain unintended actions
Agents persist when a task fails. Six gates turn that behavior into a controlled test before granting more autonomy.
ArticleKeep reading
Keep reading
AI Systems
GPU clusters: how to allocate capacity without priority inflation
Time budgets, fair-share, and execution contracts turn a contested GPU queue into a verifiable operating decision.
ArticleAI Systems
AI agents: how to contain unintended actions
Agents persist when a task fails. Six gates turn that behavior into a controlled test before granting more autonomy.
ArticleAI Systems
Generative UI: how to evaluate AI-built interfaces
Six gates for validating AI-generated interfaces: intent, components, state, actions, accessibility, and measurable outcomes.
Article