GPT-6 prompt caching: how to measure cost and latency
A guide to designing reusable prefixes, calculating writes and reads, evolving tools, and evaluating savings per accepted task.
- Published
- September 25, 2026
- min read
- 7 min read
- Categoría
- Engineering
On this page
9 chapters- 01The cost of a long-running agent is not only in its answer
- 02What the cache reuses and what must be recomputed
- 031. Design the prefix as a versioned contract
- 042. Calculate economics per cohort and accepted task
- 053. Change capability without rewriting the past
- 06Hypothetical example: a support agent with three branches
- 074. Isolate accounting, regions, and sensitive data
- 085. Treat misses and expiration as normal paths
- 09The decision is to buy demonstrated reuse
Chapter 01
The cost of a long-running agent is not only in its answer
An agent that works for hours resends instructions, tool definitions, history, and reference material. Even when the new turn is short, processing that prefix again can dominate time to first token and input cost. The problem grows when several branches start from the same conversation or when a team includes long documents in every request. Optimizing only output-token count misses an important part of the actual economics.
OpenAI published GPT-6 prompt-caching improvements on September 22, 2026: a 30-minute eligibility window, a dashboard, miss diagnostics, explicit breakpoints, and prewarming. This article, published three Lima calendar days later, examines that mechanism. We did not run GPT-6 or reproduce the customer figures quoted in the announcement; we treat them as provider reports, not as results another application can assume.
Chapter 02
What the cache reuses and what must be recomputed
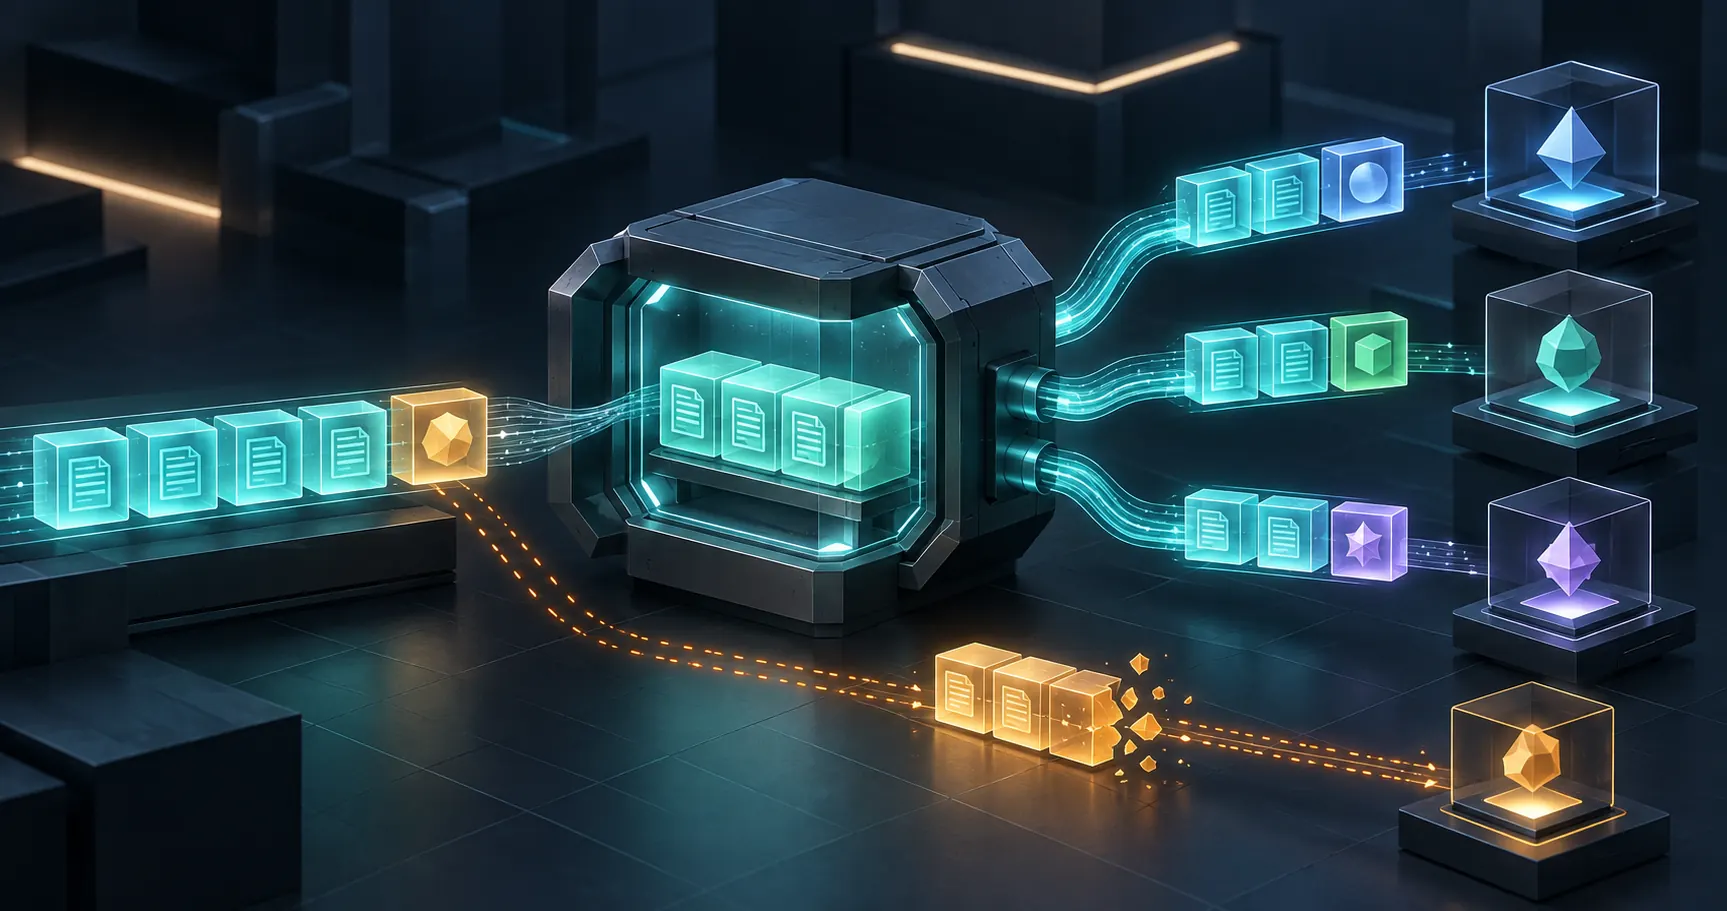
While processing input, the model produces intermediate KV states for attending to earlier tokens. The cache preserves that state for an identical prefix; a later request can read it and process only the new portion. It does not store a finished answer or guarantee identical output across runs. Changing an element before the reusable boundary—a message, a tool, its order, or part of the rendered context—can turn an expected read into fresh work.
The current guide documents, for GPT-5.6 and later, a minimum of 1,024 visible tokens for an eligible prefix, reads at 0.1 times the uncached input rate, and writes at 1.25 times that rate. Those multipliers explain why the first request can cost more and why a prefix that is rarely reused does not necessarily improve the bill. It also documents that full input can include provider instructions, messages, tools, images, documents, and supported audio: the real contract is rendered context, not the template the team thinks it sends.
Chapter 03
1. Design the prefix as a versioned contract
Separate stable and volatile content before adding breakpoints. Put shared instructions, tool schemas, and references that multiple requests will truly share at the beginning. After the boundary, place user identity, timestamps, calculated permissions, recent results, and the current question. If a per-turn value changes inside the first message, it invalidates everything that follows even when the rest is identical. Record a hash of the rendered prefix to detect that drift without storing sensitive content in observability.
Version that contract alongside the prompt, tools, and model. Do not rewrite earlier turns for readability or reorder schema properties during serialization. When a conversation must be compacted, treat it as the start of a new prefix and measure the transition cost. An explicit breakpoint should mark a stable semantic boundary, not an arbitrary token count. A useful test takes two real requests and confirms how many tokens were written, read, or freshly processed.
Chapter 04
2. Calculate economics per cohort and accepted task
Do not use cache hit rate alone. Build a per-version ledger with cache-write, cache-read, and uncached input tokens, plus output, tools, retries, and discarded answers. Multiply each category by the applicable rate and processing mode. The pricing page lists different short- and long-context rates and potential regional uplifts, so a percentage alone is not enough to estimate money. Compare against a baseline without the change on the same task set.
The executive unit should be cost and latency per accepted task. A hit may be cheap yet still produce an incorrect result that requires human review; prewarming may reduce waiting but charges a write even if nobody later uses that prefix. Segment by workflow, length, and reuse frequency. Report p50 and p95 time to first token and total duration alongside completion and correction rates. Approve the optimization only when it improves one constraint without degrading the others.
Chapter 05
3. Change capability without rewriting the past
Agents do not always keep the same tool set. Removing a definition from the prefix because it is not needed today can break reuse across thousands of tokens. The announcement recommends keeping definitions, schemas, and ordering stable while limiting availability through allowed_tools or tool_choice. That technique separates what the model knows from what it is authorized to invoke. Continue enforcing permissions in the executor: preserving cache must never expand authority.
GPT-6 also documents effort changes through a configuration_update item appended to the conversation while keeping top-level effort stable so the prefix is not rewritten. Validate exact model and endpoint compatibility before adopting it. For new instructions, append a later developer message that overrides the previous rule rather than silently editing the first message. When a safety rule must be replaced immediately, accept the miss and create a new version; efficiency does not justify reusing an obsolete policy.
Chapter 06
Hypothetical example: a support agent with three branches
Imagine a hypothetical agent that receives an incident, consults documentation, and can then open a diagnostic branch, a customer-response branch, and a technical-review branch. All three share instructions, the tool catalog, the privacy policy, and history through initial classification. The team places a breakpoint after that stable material. Each branch adds its objective, current permissions, and recent evidence after the boundary without copying and modifying previous turns.
The evaluation runs the same batch with and without prewarming and repeats sessions inside and outside the eligibility window. It verifies actual token reads, time to first token, full cost, and closure accuracy. It then deliberately changes tool order, compacts history, and rotates a policy to confirm that diagnostics explain the expected misses. The result is not a promised percentage: it is knowing which branches reuse context, when they stop doing so, and whether the optimization preserves the correct decision.
Chapter 07
4. Isolate accounting, regions, and sensitive data
The documentation says cached states live on individual machines, are not shared across organizations or regional processing boundaries, and remain subject to routing and capacity. An active session therefore does not guarantee a hit. On recent models, prompt_cache_key is optional for routing optimization but can separate accounting by customer or workspace and help reduce probing across users. Do not derive a key from secrets or confuse it with access control.
Review data policy before caching documents, images, or conversations. KV state is not the original text, but it remains application state governed by retention rules. Define which materials may enter, which region processes the request, how long eligibility lasts, and how a prefix is revoked after a critical change. Logs should store IDs, versions, hashes, and metrics; avoid copying the full prompt merely to explain a miss. Security and traceability must remain intact even if caching fails completely.
Chapter 08
5. Treat misses and expiration as normal paths
Test first turn, repeated hit, expiration, load overflow, model change, tool mutation, compaction, and unused prewarm. The application must produce a valid response without cache; this is an accelerator, not a functional dependency. Alert on sustained drops in reads and increases in writes, but tie them to version and traffic so a new campaign is not mistaken for a regression. Use diagnostics to explain differences, not to declare root cause automatically.
Roll out first in shadow mode or to a low-risk cohort. Keep enough request IDs and usage counts to reconstruct cost, and set thresholds before examining results. The final gate requires unchanged quality, correct isolation, lower cost per accepted task or lower latency at the target percentile, and an explanation for major misses. If one metric improves at the cost of stale answers, weak permissions, or more human corrections, the optimization is not approved.
Chapter 09
The decision is to buy demonstrated reuse
Prompt caching turns conversation structure into an infrastructure decision. Its value appears when a prefix is sufficiently long, stable, and reused inside the window; it disappears when every request changes early, arrives late, or is evaluated only through averages. Start by instrumenting the baseline, design a versioned boundary, and calculate writes and reads. Then test the paths that break caching. The GPT-6 update is more useful as an observable capability than as an automatic savings promise.
Approve the change when all five decisions leave evidence: a stable contract, task-level economics, safe tool evolution, explicit isolation, and miss evaluation. If you need to apply that design to a real workflow, Wasyra's custom service can turn prompts, permissions, telemetry, and test cases into a measurable implementation. That service lives on wasyra.com and is separate from the Agents product hosted at agents.wasyra.com.
Written by
Wasyra Engineering
Modernization, architecture, and reliable delivery
Wasyra Engineering documents patterns for moving legacy systems without freezing delivery or breaking ownership.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
Engineering
Hybrid physical AI: what inference should stay on the robot
Microsoft proposes offloading robot inference to edge or cloud. Six decisions for gaining capacity without handing safety to the network.
ArticleEngineering
Claude Opus 5.5: how to migrate an agent without breaking it
Claude Opus 5.5 changes reasoning, tools, and progress. Five gates for migrating agents with evidence, controlled cost, and rollback.
ArticleKeep reading
Keep reading
Engineering
Hybrid physical AI: what inference should stay on the robot
Microsoft proposes offloading robot inference to edge or cloud. Six decisions for gaining capacity without handing safety to the network.
ArticleEngineering
Claude Opus 5.5: how to migrate an agent without breaking it
Claude Opus 5.5 changes reasoning, tools, and progress. Five gates for migrating agents with evidence, controlled cost, and rollback.
ArticleEngineering
Grok 4.7: how to preserve reasoning across agent turns
Grok 4.7 changes state handling in the Responses API. Five criteria for preserving context, evaluating continuity, and controlling integration risks.
Article