Decisions API: seven gates for production
OpenAI made the Decisions API generally available for turning text, images, and JSON into predicates, choices, or scores. This guide explains where the endpoint fits, how to separate classification from execution, and what evaluation a decision needs before entering a product's critical path.
- Published
- min read
- 8 min read
- Categoría
- AI Systems
On this page
8 chapters- 01When should you use the Decisions API?
- 02How a bounded decision works
- 03Hypothetical example: routing a return
- 04When do you need Responses, rules, or review?
- 05Seven gates before automation
- 06How do you evaluate confidence and thresholds?
- 07Cost, caching, and operating risks
- 08The decision is the product, not the endpoint
Chapter 01
When should you use the Decisions API?
The Decisions API fits when an application must answer a frequent question from a closed set of outcomes and speed matters: test a condition, choose a route, or score against a rubric. The contract must be writable before the model call, errors must be measurable with labeled examples, and an uncertain answer needs a safe exit. It does not replace generation, open-ended extraction, or tools. OpenAI announced general availability on October 22, 2026, two days before this publication in America/Lima, with GPT-6 Luna, text, image, or JSON inputs, and up to 400 questions per request. The release lowers technical friction for placing classifiers in interactive paths, but it does not remove the product work: define non-overlapping options, calibrate thresholds by error cost, separate the answer from the action, and watch for distribution shifts. Responsible architecture starts with one narrow, reversible decision rather than turning every workflow step into an inference.
The announcement says the endpoint delivers bounded decisions up to ten times faster than GPT-6 Luna through the Responses API. It also publishes customer cases with latency or cost improvements. These are provider and workload-specific results, not a promise for every system. A team should treat them as a reason to run its own experiment: the same evidence, taxonomy, case set, and measurements for p50, p95, quality, and review rate. The useful comparison is not “Decisions versus a slow model”; it is the new route versus the system that handles that decision today, including deterministic code when code is enough.
The ideal candidate occurs often, tolerates a bounded output, and currently pays latency to generate text nobody needs. A poor candidate must explain a policy, draft a response, gather missing data, execute a tool, or chain dependent reasoning. In those cases, a fast decision may contribute a signal, but it should not pretend to have completed the work. The architectural gain arrives when a small contract reduces variability and cost without erasing context, oversight, or accountability.
Chapter 02
How a bounded decision works
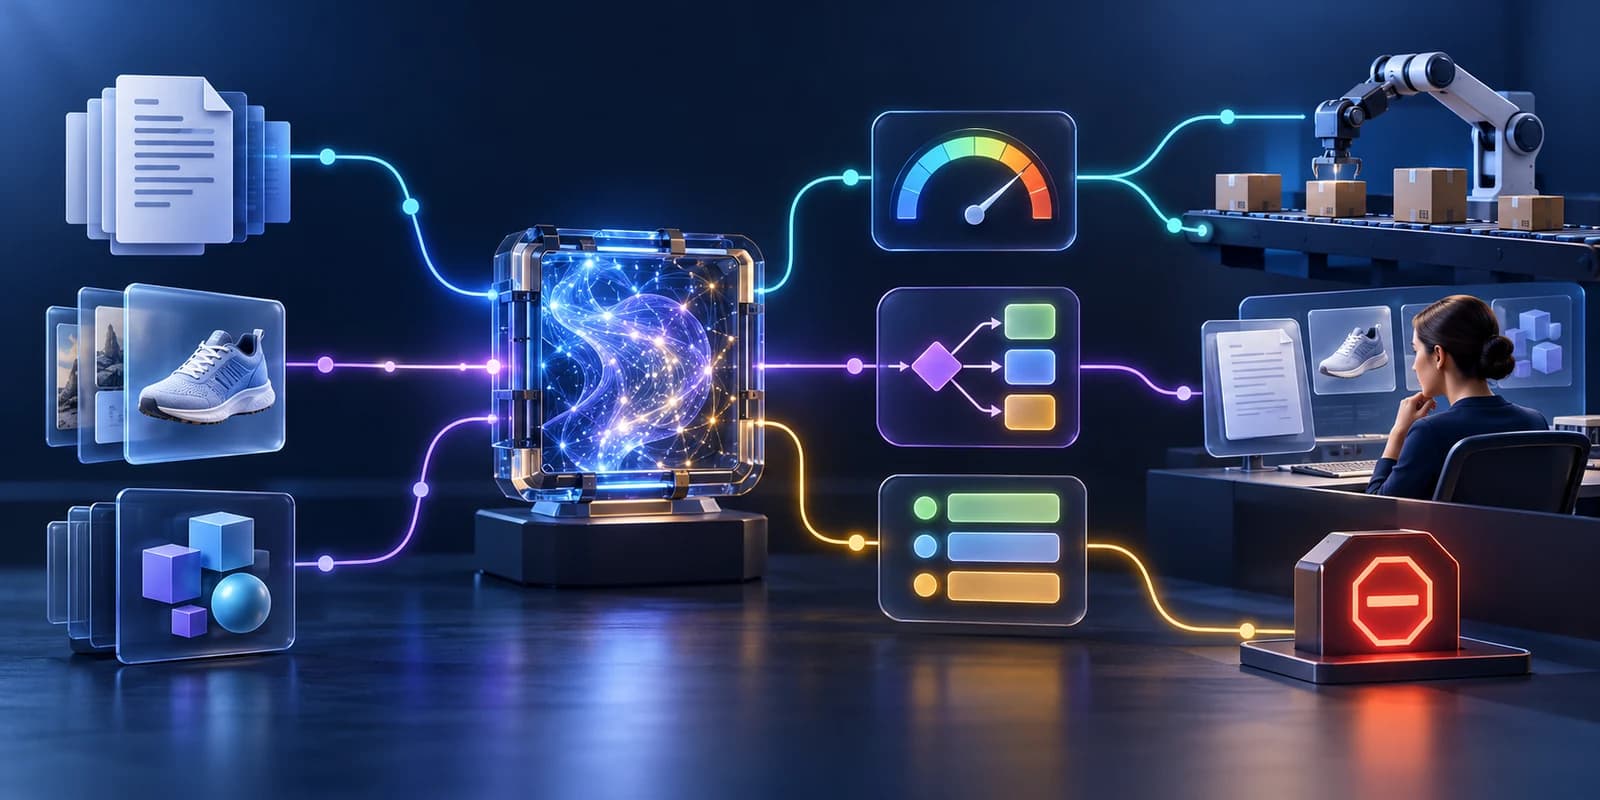
A request separates shared evidence from questions. The evidence can be text, messages with tool history, images, or structured data. Each question gets a stable name, instructions, and an answer type. Predicate estimates the probability of a condition; choice distributes probability across unordered options; score computes a value over ordered levels. The service returns an answer array associated with those names, allowing code to consume a small contract instead of parsing free-form prose.
The documentation allows independent questions about the same evidence to be grouped. This can save transport and reuse context, but it does not turn a batch into a reasoning graph. If the second question depends on the first, OpenAI says to send separate requests. That boundary matters: asking “is there damage?” and “which repair applies?” at the same time can hide that the second is meaningless when no damage exists. The application must represent the dependency, persist the first answer, and decide whether to ask the next question.
| Type | Use it for | Do not confuse it with |
|---|---|---|
| Predicate | An observable condition with a threshold | Automatic authorization |
| Choice | Mutually distinguishable options | Free text or overlapping categories |
| Score | Ordered levels with explicit criteria | A physical measure or calibrated probability |
Chapter 03
Hypothetical example: routing a return
Imagine a retailer receiving a product photo, the buyer's written reason, SKU, and order history. This example is hypothetical. A first predicate question estimates whether the image shows visible damage. A choice classifies the request as damage, size, incomplete delivery, buyer's remorse, or other. A score ranks review urgency against a defined rubric. The answer does not approve the refund: it produces signals for business rules that combine deadline, amount, known fraud, inventory, and regional policy.
The contract needs three exits beyond the happy categories. “Insufficient evidence” covers unreadable photos or missing fields. “Outside taxonomy” prevents forcing a new case into the nearest option. “Human review” receives low-confidence or high-impact answers. Every signal preserves the instruction version, model, evidence hash, and the application's later action. The team can then reconstruct why a case took a route, reevaluate it under a new version, and measure whether automation reduced work without increasing expensive errors.
Chapter 04
When do you need Responses, rules, or review?
Decisions answers closed questions. Structured Outputs with Responses fits when you need to generate your own object with variable fields, extraction, or explanation. Function calling fits when the model must request a tool with arguments. Deterministic rules still win when the answer lives in exact data: allowed country, expired date, amount above a limit, or a role without permission. A human reviewer enters when error carries legal, financial, physical, or reputational cost that the evaluation set does not yet control.
A practical architecture uses layers. First validate schema, permissions, and hard conditions in code. Then use Decisions only for semantic ambiguity that code handles poorly. A policy combines that signal with operational context and selects automation, review, or safe rejection. Finally, Responses can draft an explanation grounded in already-decided data without silently deciding again. This separation makes each responsibility observable and prevents fluent wording from changing a business rule.
| Need | Mechanism | Primary gate |
|---|---|---|
| Exact fact or hard policy | Deterministic code | Rule and data tests |
| Condition, category, or level | Decisions API | Error matrix and thresholds |
| Object, explanation, or text | Responses API | Schema, groundedness, and quality |
| External action | Tool plus authorization | Permissions, idempotency, and audit |
Chapter 05
Seven gates before automation
Speed creates value only when the contract, quality, and failure path are defined. These seven gates turn a classification demo into an operable decision.
First, fix the scope: one observable question and one reversible action. Second, design the taxonomy: options that cover the known domain, remain distinguishable, and include an unknown exit. Third, version evidence and instructions so every answer can be reproduced. Fourth, build a labeled set containing common cases, edge cases, incomplete data, and out-of-distribution examples. These four gates prove the team knows what it is asking and can recognize a wrong answer.
Fifth, calibrate thresholds against the cost of false positives and false negatives; one global number rarely serves every route. Sixth, separate decision from effect with explicit policy, idempotency, and authorization for sensitive actions. Seventh, operate the path: observe latency, errors, abstentions, class mix, review, and drift; define rollback to rules, the previous system, or full review. No provider benchmark replaces these gates because none knows the cost of being wrong in your product.
- Narrow, reversible scope
- Taxonomy with unknown and insufficient-evidence exits
- Reproducible versioning
- Representative labeled set
- Thresholds by error cost
- Separate policy and authorization
- Observability, drift, and rollback
Chapter 06
How do you evaluate confidence and thresholds?
Start with a confusion matrix by class and relevant segment rather than aggregate accuracy. For a predicate, plot precision and recall at several thresholds. For choice, inspect confusion between every pair of options and the relationship between confidence and correctness. For score, measure whether adjacent levels preserve the expected order and whether the average hides disagreement between extremes. Separate cases where the system abstains: routing them to review is valid behavior, not an error to hide.
Run in shadow mode first. The new path answers, but the previous system retains authority. Compare decisions and collect human adjudication on disagreements. Then enable only a low-risk band: cases with complete evidence, a known class, and sufficient margin. Keep a holdout that is not used to tune instructions, and rerun evaluation whenever the model, questions, options, input, policy, or population changes. The official Node SDK released on October 22 widened accepted instruction and input types; even a compatible change can break code that assumed strings or closed roles, so the integration also needs contract tests.
Chapter 07
Cost, caching, and operating risks
At publication time, OpenAI lists USD 0.10 per million input tokens and USD 0.01 for cached input, with no output-token charge. Prices change, so confirm the current page before budgeting. Model cost per accepted decision rather than per call. Include tokens, cache writes, retries, grouped questions, review rate, and human cost. Caching helps when a shared prefix of at least 1,024 tokens remains identical; it does not justify inflating context or hiding changing data behind a stable key.
Operating risks are less flashy than latency. A timeout does not mean false; invalid JSON does not mean other; a new class must not silently fall into the nearest option. Record transport failure, provider failure, abstention, low confidence, and policy rejection as distinct states. Limit concurrency, use backoff, protect sensitive data, and monitor usage by project or key. If the decision sits on the hot path, rehearse degradation: conservative rules, a review queue, or a partial experience. The application must remain safe when the model does not answer.
Chapter 08
The decision is the product, not the endpoint
The Decisions API opens an attractive path for interactive classification and scoring: a small contract, multimodal input, multiple independent questions, and focused cost. Its value is not wholesale replacement of Responses, but extracting repetitive decisions that can already be named, labeled, and evaluated. The narrower the question, the clearer it becomes when an answer is wrong and the easier it is to design a fallback.
Start with one high-volume, low-impact decision. Write the taxonomy, label real cases, measure against the current path, and run in shadow mode. Automate only the segment whose error cost is controlled; retain review, versioning, and rollback. If your team needs to turn an ambiguous workflow into evaluable contracts, Wasyra can help design the architecture and pilot without confusing a model signal with authority to act.
Written by
Wasyra Lab
AI systems and operations architecture
Wasyra Lab publishes practical frameworks for designing AI agents, automations, and operating flows that survive production.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
AI Systems
Distributed agents: when to parallelize analysis
More agents help only when work can be split without losing evidence. Seven decisions turn parallelism into evaluable coverage.
ArticleAI Systems
Multimodal RAG: seven gates for trusting the evidence
Parsing, retrieving, and reranking are different contracts. Seven gates help decide whether a multimodal stack improves evidence without hiding new failure modes.
ArticleKeep reading
Keep reading
AI Systems
Distributed agents: when to parallelize analysis
More agents help only when work can be split without losing evidence. Seven decisions turn parallelism into evaluable coverage.
ArticleAI Systems
Multimodal RAG: seven gates for trusting the evidence
Parsing, retrieving, and reranking are different contracts. Seven gates help decide whether a multimodal stack improves evidence without hiding new failure modes.
ArticleAI Systems
Synthetic multilingual data: six release gates
Translating millions of documents does not create a trusted corpus. Six gates separate generation, acceptance, evaluation, and multilingual release.
Article