Distributed agents: when to parallelize analysis
OpenAI, PerturbAI, and Scripps published a biological analysis using thousands of agents in parallel. This guide separates the scientific result from the engineering pattern: independent units, evidence contracts, traceable synthesis, deduplication, budgets, and evaluation against a single agent before scaling.
- Published
- min read
- 7 min read
- Categoría
- AI Systems
On this page
7 chapters- 01When should you distribute analysis across agents?
- 02How the fan-out and fan-in pattern works
- 03Hypothetical example: reviewing thousands of suppliers
- 04Seven decisions before multiplying agents
- 05How do you evaluate a distributed-agent system?
- 06What the study does not demonstrate
- 07The decision: scale evidence, not agent count
Chapter 01
When should you distribute analysis across agents?
It makes sense when work can be divided into independent units, every unit produces verifiable evidence, a separate stage can synthesize without erasing disagreements or provenance, and a baseline shows that one agent loses coverage.
On October 21, 2026, OpenAI, PerturbAI, and Scripps Research published how they assigned thousands of agents to individual perturbations in a mouse-brain CRISPR atlas. The announcement, consulted on October 22 in America/Lima, is one day old; the original preprint is dated October 16. According to the primary sources, the agents analyzed data from millions of cells in 32 minutes, connected cellular responses with literature, and produced a reasoning atlas. At the largest workload, the distributed configuration cited more than 700 references versus 11 for the single agent, and blinded experts preferred its interpretations 75% of the time.
That demonstrates a result in one study, not a universal law that more agents are better. The useful CTO decision is narrower: if a problem contains many comparable units that one context explores superficially, parallelism can buy coverage. But if units share mutable state, depend on earlier decisions, or fail to leave structured evidence, multiplying workers also multiplies cost, contradictions, and hard-to-reproduce failures. The pattern deserves a pilot when coverage and traceability are the bottleneck, not when the task requires one coherent sequence of decisions.
Chapter 02
How the fan-out and fan-in pattern works
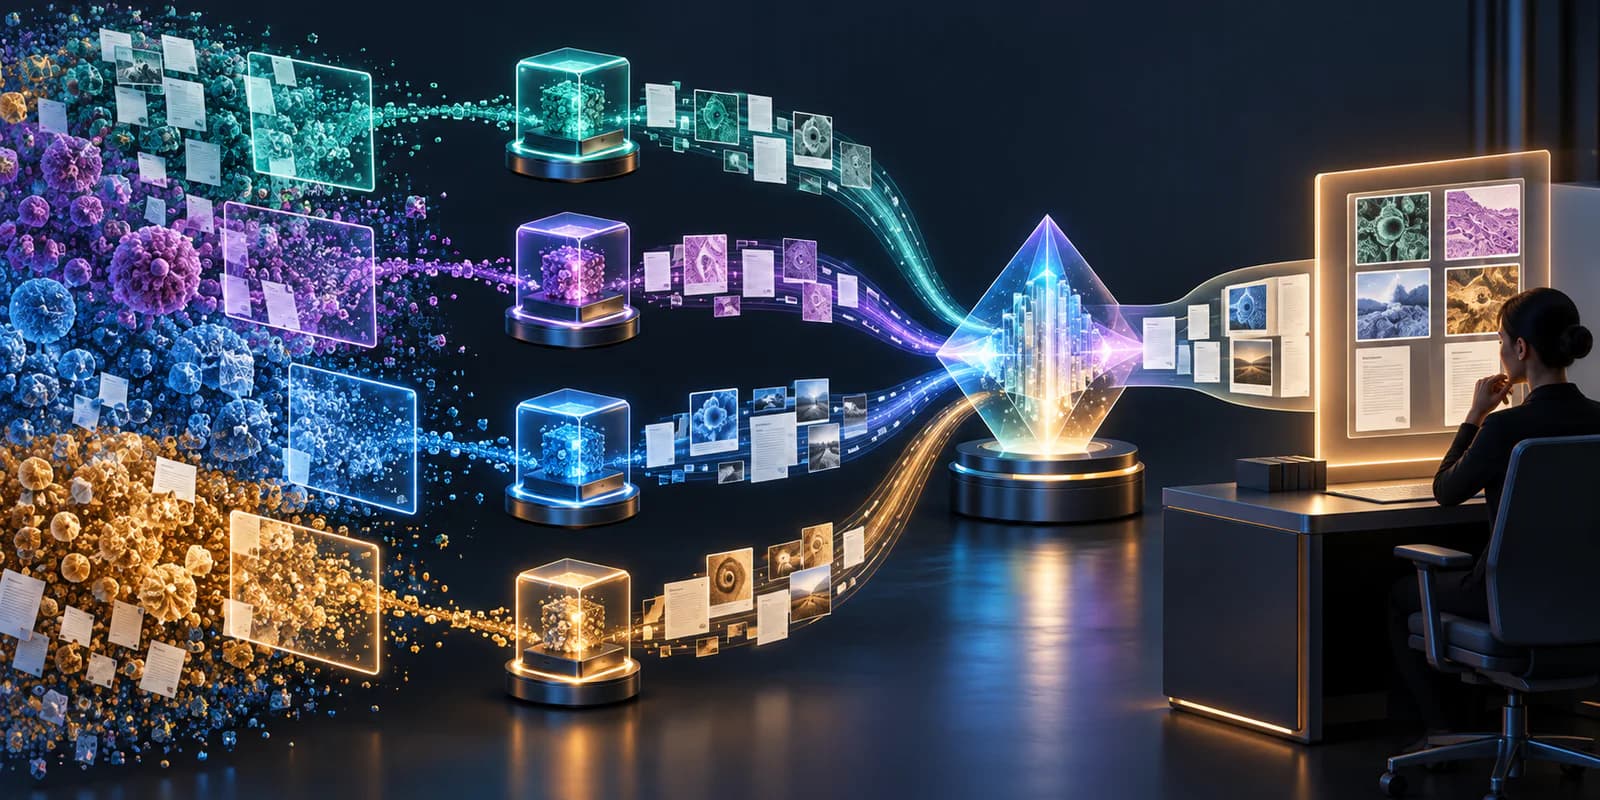
The mechanism has three contracts. First, a planner turns a broad objective into a collection of units sharing one schema. In the study, each unit represented a gene perturbation, and the worker combined expression data, cellular context, and literature search. Second, every worker emits a durable artifact: narrative findings, structured claims, citations, and measurements. The public repository preserves the runtime, corpus tools, prompts, saved reports, and analysis notebooks; that persistence makes it possible to inspect results without running inference again.
Third, a synthesizer operates on those artifacts rather than on memories from one giant conversation. It must group repeated signals, preserve opposing conclusions, weigh evidence quality, and link every summary to its source units. Fan-out expands the surface investigated; fan-in turns that breadth into a navigable result. If the synthesizer merely concatenates prose, it creates volume. If it summarizes without stable IDs, it removes auditability. And if it queries the source data again without recording changes, it creates a second analysis path that no longer matches the workers.
| Stage | Contract | Failure that must stay visible |
|---|---|---|
| Partitioning | Complete, independent, versioned units | Missing, overlapping, or dependent unit |
| Worker | Claims, evidence, citations, and explicit status | Timeout, insufficient evidence, or conflict |
| Synthesis | Summary traceable to units and sources | Duplicate, contradiction, or lost provenance |
Chapter 03
Hypothetical example: reviewing thousands of suppliers
Imagine a company that must review 4,000 suppliers before contract renewal. This example is hypothetical. Each unit contains one supplier's current contract, security file, incidents, certifications, and regional restrictions. A worker can compare that package against a shared rubric and emit claims such as “expired certification,” “missing subprocessors clause,” or “contradictory evidence,” always with file, page, date, and excerpt. Units can run in parallel because evaluating supplier A should not modify supplier B's record.
The synthesizer should not automatically decide which contracts to cancel. It can group suppliers by risk, identify patterns, and prioritize files for human review. High-impact actions remain in another system and require authorization. If two workers cite different versions of the same certificate, synthesis preserves the conflict instead of choosing the more persuasive prose. If a unit fails because of permissions or format, it appears as incomplete rather than “no findings.” Parallelism then increases coverage without turning absence of analysis into absence of risk.
Chapter 04
Seven decisions before multiplying agents
Worker count is a later parameter. First define a correct unit, an acceptable synthesis, and a visible failure.
The first decision is the partition boundary: every unit must fit in context, receive complete inputs, and avoid shared state. The second is the evidence contract: typed claims, resolvable citations, source versions, and confidence—not just a free-form report. The third is idempotency: retrying a unit must not create duplicate results or change its identity. The fourth is the synthesis algorithm: explicit rules for deduplicating, grouping, and preserving disagreement. Without those four, a large result may look exhaustive while combining gaps, replicas, and incompatible conclusions.
The fifth decision is budget: limits per unit, batch, and useful result, with cancellation when marginal evidence no longer justifies cost and latency. The sixth is isolation: authorized datasets, read-only tools where appropriate, job-scoped credentials, and no capabilities inherited for convenience. The seventh is comparative evaluation: the same task, sources, and total budget for the single-agent and distributed variants. The recent announcement held model and resources constant when comparing configurations; an enterprise pilot should follow the same principle and change one variable at a time.
- 1. Partitioning into independent, complete units.
- 2. A structured contract for claims and evidence.
- 3. Identity and idempotency for safe retries.
- 4. Synthesis that deduplicates without erasing disagreement.
- 5. Budget and a marginal-value stopping rule.
- 6. Permissions and tools isolated per job.
- 7. A controlled comparison against a single-agent baseline.
Chapter 05
How do you evaluate a distributed-agent system?
Start with stratified golden cases, not a favorable demo. Include small and large batches, abundant and sparse evidence, broken formats, contradictory sources, and answers that should abstain. Measure unit coverage, completion rate, evidence recall, claim precision, resolvable citations, duplicates, preserved contradictions, and final-ranking usefulness. Separate worker, tool, and synthesis errors; an end-to-end metric tells you whether the system works, but not which component to repair.
Then compare under three equivalent budgets: wall-clock time, tokens, or monetary cost. Parallelism may reduce elapsed time while increasing total compute, so reporting only minutes hides the economics. Track p50 and p95 per unit, queue time, retries, throttling, cost per accepted claim, and cost per case that changes a human decision. Blindly review a sample from the single-agent and distributed variants. The study's human preference result is relevant evidence, but it does not replace your own domain judges, rubrics, and work distribution.
Chapter 06
What the study does not demonstrate
The work is a preprint, not a peer-reviewed publication. It evaluates one biological atlas, one tool set, and one specific agent design; it does not prove that the pattern improves every legal, financial, or software task. The 32-minute figure describes that deployment and does not by itself disclose total cost, reserved capacity, or performance under enterprise quotas. More references do not automatically mean better conclusions either: they may repeat a source, cite weak evidence, or increase review burden.
There are systemic risks as well. Thousands of workers may share the same model bias, wrong source, or flawed rubric, producing apparent consensus. Synthesis may favor frequent claims over important exceptions. An overly broad credential turns a partitioning mistake into broad exposure. And an uncontrolled retrying batch can create a cost storm. The system therefore needs evidence diversity, adversarial sampling, concurrency limits, circuit breakers, aggregate traces, and human review focused on discrepancies and high-impact cases.
Chapter 07
The decision: scale evidence, not agent count
Approve a pilot if you can name the work unit, verify its evidence, and explain why one agent loses coverage as workload grows. Start with tens of units, not thousands. Freeze sources and rubric, run the single-agent baseline, test fan-out with a small concurrency limit, and review fan-in as an independent product. Scale only when the coverage gain survives a comparable budget, citations remain resolvable, and incomplete failures stay visible.
The recent announcement provides an important signal: for naturally separable workloads, distributing context can preserve depth where one agent compresses the search. The advantage does not come from the number itself, but from the contract that turns every investigation into an auditable artifact. If you need to design partitioning, permissions, the evidence schema, and an evaluation harness for a real process, Wasyra's custom agent service can turn this architecture into a measurable pilot. That service lives on wasyra.com and is separate from the Agents product hosted at agents.wasyra.com.
Written by
Wasyra Lab
AI systems and operations architecture
Wasyra Lab publishes practical frameworks for designing AI agents, automations, and operating flows that survive production.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
AI Systems
Multimodal RAG: seven gates for trusting the evidence
Parsing, retrieving, and reranking are different contracts. Seven gates help decide whether a multimodal stack improves evidence without hiding new failure modes.
ArticleAI Systems
AI software factory for startups: how to ship product without bloating the team
How to use an AI software factory to validate, build, and operate SaaS products with less internal team and more evidence.
ArticleKeep reading
Keep reading
AI Systems
Multimodal RAG: seven gates for trusting the evidence
Parsing, retrieving, and reranking are different contracts. Seven gates help decide whether a multimodal stack improves evidence without hiding new failure modes.
ArticleAI Systems
Synthetic multilingual data: six release gates
Translating millions of documents does not create a trusted corpus. Six gates separate generation, acceptance, evaluation, and multilingual release.
ArticleAI Systems
Continuous agent evaluation: nine release gates
An agent can respond quickly and still be wrong. Nine gates connect offline evaluation, release, production, and verifiable learning.
Article