Multimodal RAG: seven gates for trusting the evidence
NVIDIA released separate open models for parsing documents, retrieving text and images, and reranking candidates. This guide turns the advance into an evaluable architecture: stage-level contracts, retrieval metrics, provenance to the original page, domain tests, a latency budget, and an end-to-end comparison before changing production.
- Published
- min read
- 7 min read
- Categoría
- AI Systems
On this page
6 chapters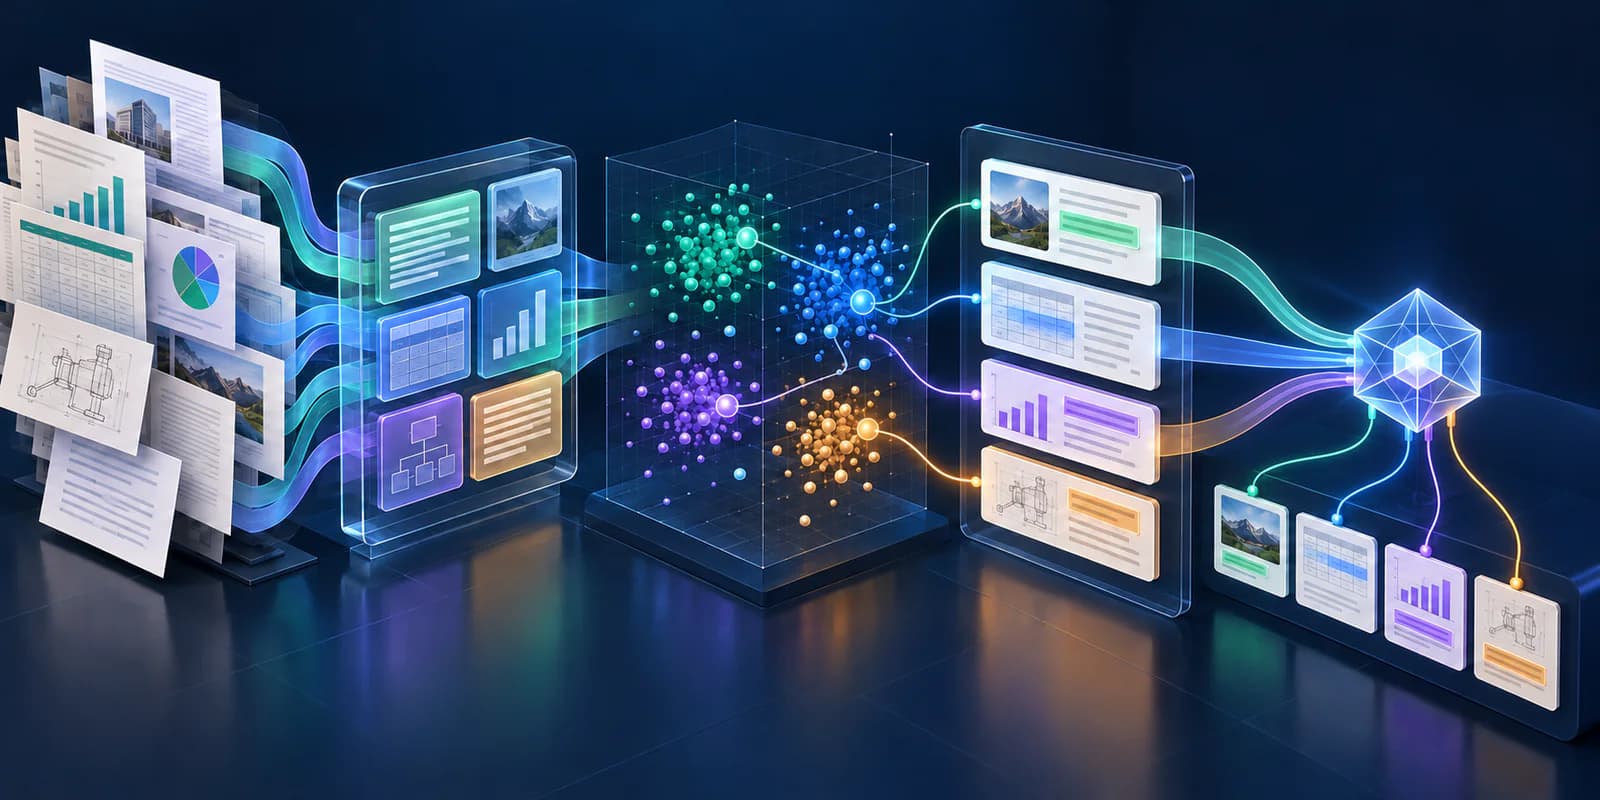
Chapter 01
When is multimodal retrieval ready?
It is ready when each stage can fail, be measured, and be replaced independently, and when the answer preserves a verifiable path to the exact document region.
On October 21, 2026, NVIDIA introduced the Nemotron 3.5 Retriever family: separate models for turning pages into structure, retrieving candidates across text and images, and reranking them before evidence reaches an agent. The announcement page was published on the day of this America/Lima consultation; the primary model cards date the Embed and Rerank weights to October 20 and Parse to October 17. The important development is not adding another model to a list. It is making explicit that a badly extracted table, a page that never entered the candidate set, and a relevant candidate ranked too low are different failures that need different diagnostics.
That separation matters because a generative model can reason only over the evidence it receives. If the pipeline drops headers, scrambles reading order, or retrieves a visually similar but semantically wrong page, asking a larger final model does not repair the broken contract. For a CTO, the useful decision is whether a staged stack raises relevant-evidence retrieval on the organization's actual documents, at acceptable latency and cost, without losing provenance. A public benchmark can justify a trial; it does not authorize a production change.
Chapter 02
Three contracts, not one RAG box
Parsing answers what is on the page and where it is. A useful parser does more than emit text: it preserves layout classes, boxes, reading order, and table or chart structure so a fragment can map back to its source. Nemotron 3.5 Parse declares those outputs and offers one-, two-, and three-pass modes. NVIDIA reports an explicit tradeoff on its reference hardware: additional passes raise the ParseBench score and reduce pages per second. The general lesson remains valuable even if another parser is chosen: precision for complex regions should be a document-type policy, not a global mode applied to every file.
Retrieval and reranking have a different contract. The embedding model encodes queries and documents separately to find a broad candidate set quickly. The reranker examines each query-document pair in more detail and changes the final order. In the announcement, NVIDIA holds the agent, tools, tasks, corpus, and execution policy fixed while changing the retrieval configuration; under that setup, it reports that adding Rerank reduced agent tokens per query by roughly 13–14% while improving retrieval accuracy. That is a result from the published experiment, not a promise for every corpus. Production teams must repeat the comparison with their own questions, formats, and languages.
Chapter 03
Hypothetical example: explaining a stockout risk
Suppose an internal agent must answer which products may run out of stock next quarter and explain why. The corpus mixes demand charts, inventory tables, scanned purchase orders, and supplier reports. During ingestion, the parser must preserve the link between each cell and its header, the unit of measure, the chart region, and the source page. The index must store visual representations and structured text together with version, permissions, and effective date. An update must not silently erase previous evidence; it should produce a new auditable version.
For a query, the embedding model retrieves a broad set: for example, reports mentioning the SKU, pages with its demand curve, and orders tied to the supplier. The reranker receives those candidates—not the whole repository—and prioritizes the ones that answer the specific relationship among demand, inventory, and lead time. The final agent gets a small package with fragments, coordinates, stage-level scores, and source references. If the answer misses a critical order, the team can ask whether the page was parsed, whether it appeared in the initial top-k, and whether it lost rank during reranking. Without that chain, the team sees only a wrong answer and cannot tell which component to fix.
Chapter 04
Seven gates before changing production
Acceptance must measure the full journey while preserving layer-level metrics. One final average cannot locate regressions.
Build the evaluation set from authorized real queries, with relevance judged by people who understand the domain. Include text, tables, charts, scans, multiple versions, negation, and questions whose correct answer is insufficient evidence. Separate training, tuning, and evaluation so synthetic queries used to adapt the retriever do not also become its exam. For every case, preserve the expected page, useful region, and reason for relevance; this lets you measure candidate-set recall, ranking quality, and citation fidelity without depending on the generative model yet.
Then run an offline A/B comparison between the current and candidate stacks using the same frozen corpus, permission policy, and final agent. Record p50 and p95 latency, GPU use, processed documents, agent tokens, and errors by type. Only then run a shadow test with representative traffic while preventing the new stack from answering users. Rollout starts with bounded collections and can return to the prior configuration without reindexing everything. Every gate needs an owner, a threshold, and rollback evidence; otherwise it is advice, not a release control.
- Gate 1 — Parsing fidelity: tables, charts, reading order, boxes, and text preserve meaning and location.
- Gate 2 — Candidate coverage: judged-relevant evidence appears in the top-k before reranking.
- Gate 3 — Ranking quality: the reranker raises direct evidence without displacing needed diversity.
- Gate 4 — Provenance: every claim maps back to an authorized file, version, page, and region.
- Gate 5 — End-to-end outcome: the real task improves and abstains when evidence is missing.
- Gate 6 — Operating budget: latency, compute, storage, and tokens fit the SLO and target cost.
- Gate 7 — Security and rollback: permissions, deletion, reindexing, observability, and return are rehearsed.
Chapter 05
Implementation decisions not to delegate to the model
Define the evidence unit first. A full page preserves visual context but may dilute a small clause; a crop improves precision but may separate a value from its header. Store both and link them. Also decide which documents need a second or third pass, how many candidates each query class retrieves, how many the cross-encoder reranks, and what minimum diversity must survive. Those parameters belong in a versioned policy. If they change without recording the index, results stop being reproducible and regressions look random.
Do not mix authorization with similarity. Permission filtering must limit the universe before evidence reaches the agent and remain in force during reranking; a relevant result does not gain access by receiving a high score. Also retain the original file version, hash, ingestion timestamp, applied policy, and region coordinates. The Embed model states that its text component remains compatible with the previous generation, which may lower the cost of a text transition; still verify that compatibility against your serialization, selected dimensions, and vector engine before reusing an index.
Chapter 06
Limits, risks, and the final decision
The published results come from NVIDIA and specific benchmarks. ViDoRe, ParseBench, BRIGHT, and BrowseComp-Plus do not automatically represent an organization's contracts, drawings, invoices, or case files. The model cards describe a mix of public, synthetic, and labeled data and warn that integration requires use-case-specific testing. There is also an operating dependency: the reported profiles use NVIDIA GPUs and specific Transformers or vLLM versions; the Rerank card even documents serving paths that can mishandle image placeholders. Licensing, isolation, observability, patching, and hardware capacity are part of the decision, not later work.
The conclusion is not that every company should adopt this family. It is that multimodal retrieval can now be evaluated as a chain of replaceable contracts. Run a pilot if you currently lose information in tables or charts, cannot trace an answer to the original page, or spend tokens because the agent repeats searches. Keep the current stack if the evaluation set shows no material improvement or if latency and operating burden outweigh the benefit. If you need to design the corpus, permissions, harness, and rollout as one system, Wasyra can help turn the experiment into a verifiable decision without confusing a demo with production.
Written by
Wasyra Lab
AI systems and operations architecture
Wasyra Lab publishes practical frameworks for designing AI agents, automations, and operating flows that survive production.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
AI Systems
AI software factory for startups: how to ship product without bloating the team
How to use an AI software factory to validate, build, and operate SaaS products with less internal team and more evidence.
ArticleAI Systems
Top 5 AI and product development news to watch now
Five recent moves from OpenAI, GitHub, AWS, and Anthropic that change how teams design, build, and operate software.
ArticleKeep reading
Keep reading
AI Systems
Synthetic multilingual data: six release gates
Translating millions of documents does not create a trusted corpus. Six gates separate generation, acceptance, evaluation, and multilingual release.
ArticleAI Systems
Continuous agent evaluation: nine release gates
An agent can respond quickly and still be wrong. Nine gates connect offline evaluation, release, production, and verifiable learning.
ArticleAI Systems
Open-weight models: five gates before self-hosting
Owning the weights is not the same as controlling the system. Five gates to decide whether an open-weight model deserves your infrastructure.
Article