Claude Sonnet 5.5: calibrate effort without overreach
A guide to turning effort levels into an evaluable policy: segment tasks, measure complete outcomes, and escalate only when evidence supports it.
- Published
- September 29, 2026
- min read
- 6 min read
- Categoría
- AI Systems
On this page
8 chapters- 01The maximum level can be the wrong setting
- 02The mechanism: effort expands behavior, not just tokens
- 031. Define the task envelope before sweeping levels
- 042. Evaluate an acceptance vector, not an average score
- 053. Treat scope, tools, and time as budgets
- 064. Escalate on observable signals and step back down
- 075. Hypothetical example: resolving an invoice dispute
- 08Conclusion: buy acceptance, not activity
Chapter 01
The maximum level can be the wrong setting
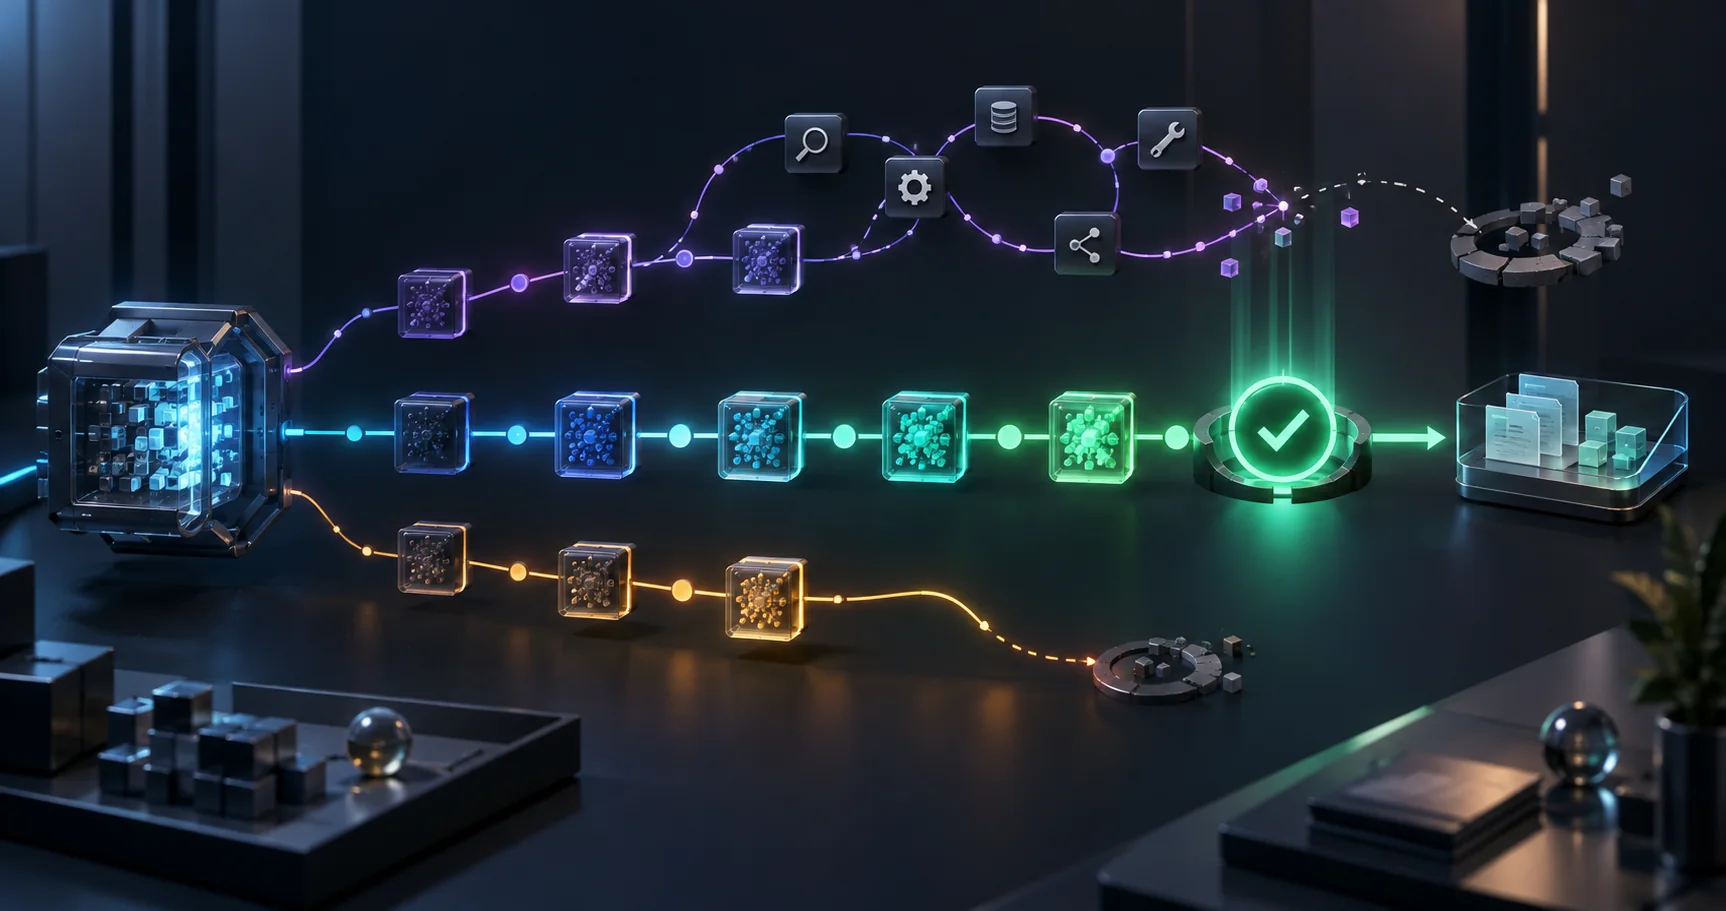
When an agent fails a complex task, raising effort looks like the obvious correction. The model reasons longer, explores more paths, and reviews more deeply. But a real operation does not reward activity; it rewards an acceptable outcome within the agreed scope, time, and budget. If the agent adds unrequested files, starts unnecessary review rounds, or exhausts the timeout, more work can reduce the chance of acceptance.
Anthropic released Claude Sonnet 5.5 on September 28, 2026 and documented five effort levels. The official release claims higher speed and lower cost per task than Sonnet 5, but these are vendor measurements we did not reproduce. The more useful engineering signal is different: on FrontierCode, max effort scored below xhigh because some runs started subagent reviews, timed out, or made out-of-scope changes. This article is published one Lima calendar day later.
Chapter 02
The mechanism: effort expands behavior, not just tokens
Effort controls how much reasoning and autonomy the model dedicates to a request. In Sonnet 5.5, low, medium, high, xhigh, and max are not fixed budgets and do not map directly to levels from an earlier version. With more effort, the agent can sustain a longer task, check its work, and resolve ambiguity; it can also interpret an open request as permission to add related documentation, tests, or refactors. The control changes the full trajectory, including tools, retries, and stopping decisions.
That is why the comparison unit should not be an isolated answer or token count. It should be the completed and accepted task: fixed input, allowed actions, expected artifact, required checks, and rejection criteria. Two levels may produce correct code, but only one may keep the diff scoped and finish before the limit. On another task, the lower level may stop too early. The right policy depends on the shape of the work, not on a universal intelligence hierarchy.
Chapter 03
1. Define the task envelope before sweeping levels
First separate workloads that genuinely require different behavior. Fixed-schema extraction, a sourced support reply, a one-file patch, and an ambiguous migration should not share the same default merely because they call the same model. For each class, record input size, available tools, reversibility, error cost, maximum duration, expected artifact, and whether a person can clarify uncertainty. That envelope turns the word 'complex' into observable constraints.
Then create representative and boundary cases inside each class. Keep the same inputs, tool versions, limits, and graders while comparing effort. Include incomplete requests, contradictory data, an unavailable dependency, and a case that must request approval. If you change the prompt, model, harness, and level at the same time, you will not know what caused an improvement. The sweep should isolate one decision and leave a reproducible baseline.
Chapter 04
2. Evaluate an acceptance vector, not an average score
Define independent gates: functional correctness, scope compliance, valid tool use, sufficient evidence, latency, total cost, and required human correction. An outcome fails if it breaks a critical contract even when its average is high. For code, for example, separate passing tests, allowed files, absence of side changes, review acceptance, and cycle time. For support, separate factual accuracy, citations, privacy, tone, and correct escalation.
Measure variability as well. Run each case multiple times when risk and budget allow, because a single trajectory can hide a problematic tail. Report complete acceptance, not merely the percentage of correct answers, and retain rejection reasons. The release question is 'Which level crosses every gate with enough stability?' rather than 'Which level achieved the highest aggregate score?' That distinction avoids buying reasoning that does not improve the operational outcome.
Chapter 05
3. Treat scope, tools, and time as budgets
Do not limit only tokens. Set maximum tool calls, duration, modifiable files or records, attempts per dependency, and self-review rounds. The agent should know the stopping condition and the next safe state: deliver the artifact, ask for clarification, escalate, or abort without effects. High effort without these edges can turn diligence into drift. Low effort without a completion criterion can return a plan when the contract required execution.
The Sonnet 5.5 guidance acknowledges that xhigh and max can initiate extra review and related actions. Anthropic suggests instructing the agent to stop when the task and its checks are complete and not to launch reviewers unless requested. That pattern generalizes: the prompt bounds initiative while the runtime enforces limits the prompt cannot guarantee. Keep both, because a sentence does not replace quotas, permissions, or effective cancellation.
Chapter 06
4. Escalate on observable signals and step back down
Start each class at the lowest level that clears its gates, not at the highest available level. Escalate when a defined signal appears: an incomplete plan, unresolved dependency, failed verification, material uncertainty, or a task crossing a length threshold. Do not escalate out of frustration after every error; some failures require better context, a repaired tool, or human approval, and more effort will only repeat the problem at higher cost.
Record the initial level, escalation reason, tools already used, reversible state, and final outcome. Escalation must not erase the first attempt or duplicate effects. Re-evaluate periodically and step effort down when the prompt, tools, or model improve. A policy that only permits increases turns every system improvement into permanent cost. The router should learn the complexity it needs rather than confusing age with criticality or volume with difficulty.
Chapter 07
5. Hypothetical example: resolving an invoice dispute
Suppose an agent receives a dispute, checks the contract and invoice, proposes a reply, and creates a task when it finds an inconsistency. Field extraction starts at low; analysis with two consistent documents starts at medium. If commercial terms conflict, the router moves to high with the same snapshot and requires a citation for every conclusion. No level may issue a credit note: that action sits outside the envelope and requires finance approval.
The team compares five gates: correct fields, traceable evidence, escalation decision, response within the SLA, and zero unauthorized effects. If high improves conflict handling but creates duplicate tasks, it is not approved until idempotency is fixed. If xhigh offers a more elegant explanation but takes too long without changing acceptance, high remains. If max searches unrequested attachments, the scope gate rejects it even when the answer is correct. This scenario is illustrative and does not represent a Wasyra customer or Wasyra results.
Chapter 08
Conclusion: buy acceptance, not activity
Anthropic's published results depend on its harnesses, graders, prompts, and pre-release deployments. We did not run Sonnet 5.5 or verify its speed, cost, or benchmark claims. Nor do we assume the anomaly between max and xhigh will appear in another workload. The transferable lesson is methodological: an effort control can change scope, tools, and stopping behavior, so it must be evaluated as a complete execution policy.
Approve a level when it clears every relevant gate with acceptable variability and sustainable total cost. Keep an explicit path to escalate and another to stop. Repeat the sweep when the model, prompt, tools, limits, or case distribution changes. Retain rejected runs as well; they often reveal whether the next step is more reasoning, better context, a runtime control, or a human decision.
A good router does not assume more is better. It selects the minimum effort that completes the task, preserves scope, and leaves reviewable evidence. If you need to turn that policy into a pilot with real cases, permissions, and release gates, Wasyra's custom agent service can design the path. It is an implementation service separate from the product available at agents.wasyra.com.
Written by
Wasyra AI Systems
Trust, copilots, and enterprise adoption
Wasyra AI Systems covers guardrails, suggestion-first modes, and review design so work assistants earn real adoption.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
AI Systems
HydraFusion: how to evaluate multi-model orchestration
Single, cascade, or critique are not magic shortcuts. Five gates measure quality, cost, latency, isolation, and repository state.
ArticleAI Systems
Chat-to-code agents: how to preserve context provenance
GitHub connected more Slack and Teams context to executable work. Five controls preserve provenance, scope, and a revocable outcome.
ArticleKeep reading
Keep reading
AI Systems
HydraFusion: how to evaluate multi-model orchestration
Single, cascade, or critique are not magic shortcuts. Five gates measure quality, cost, latency, isolation, and repository state.
ArticleAI Systems
Chat-to-code agents: how to preserve context provenance
GitHub connected more Slack and Teams context to executable work. Five controls preserve provenance, scope, and a revocable outcome.
ArticleAI Systems
AI agents: how to prove a runtime policy works
Microsoft joined discovery, evaluation, and runtime policy. Six decisions turn the loop into release evidence instead of a demo.
Article