ReviewBench: how to evaluate a code review agent
ReviewBench turns code review agent evaluation into a reproducible system. This guide explains what to adopt, what not to mistake for certainty, and how to connect an offline benchmark with the team's real work.
- Published
- min read
- 8 min read
- Categoría
- Engineering
On this page
10 chapters- 01An agent that comments often does not necessarily review well
- 02The mechanism: freeze the work and evaluate atomic findings
- 03Decision 1: represent your workload, not the most convenient distribution
- 04Decision 2: build ground truth from sources that disagree
- 05Decision 3: calibrate and version the automated judge
- 06Decision 4: choose an operating point, not a magic score
- 07Hypothetical example: evaluate before enabling a merge gate
- 08Decision 5: require correspondence with production
- 09Limits that must be written down
- 10The decision is not to buy a score, but to build measurable trust
Chapter 01
An agent that comments often does not necessarily review well
A code review agent demo is often convincing: it opens a pull request, flags a race condition, and proposes a change. The problem appears when deciding whether it should review every repository, block merges, or replace part of human work. Counting comments favors the most verbose system; counting known bugs ignores new findings; asking whether a comment sounds reasonable rewards writing rather than usefulness. Without an evaluation contract, every prompt improvement can move one metric while making the real experience worse.
GitHub published ReviewBench on October 5, 2026 as an open research preview for comparing reviewers on real pull requests. The important contribution is not an isolated ranking. It is an auditable chain across corpus, findings, truth criteria, matcher, judge, and metrics, plus a separate check against online experiments. For a CTO, the useful question is not who ranks first today, but which parts of that chain must be reproduced before turning an agent into a quality gate.
Chapter 02
The mechanism: freeze the work and evaluate atomic findings
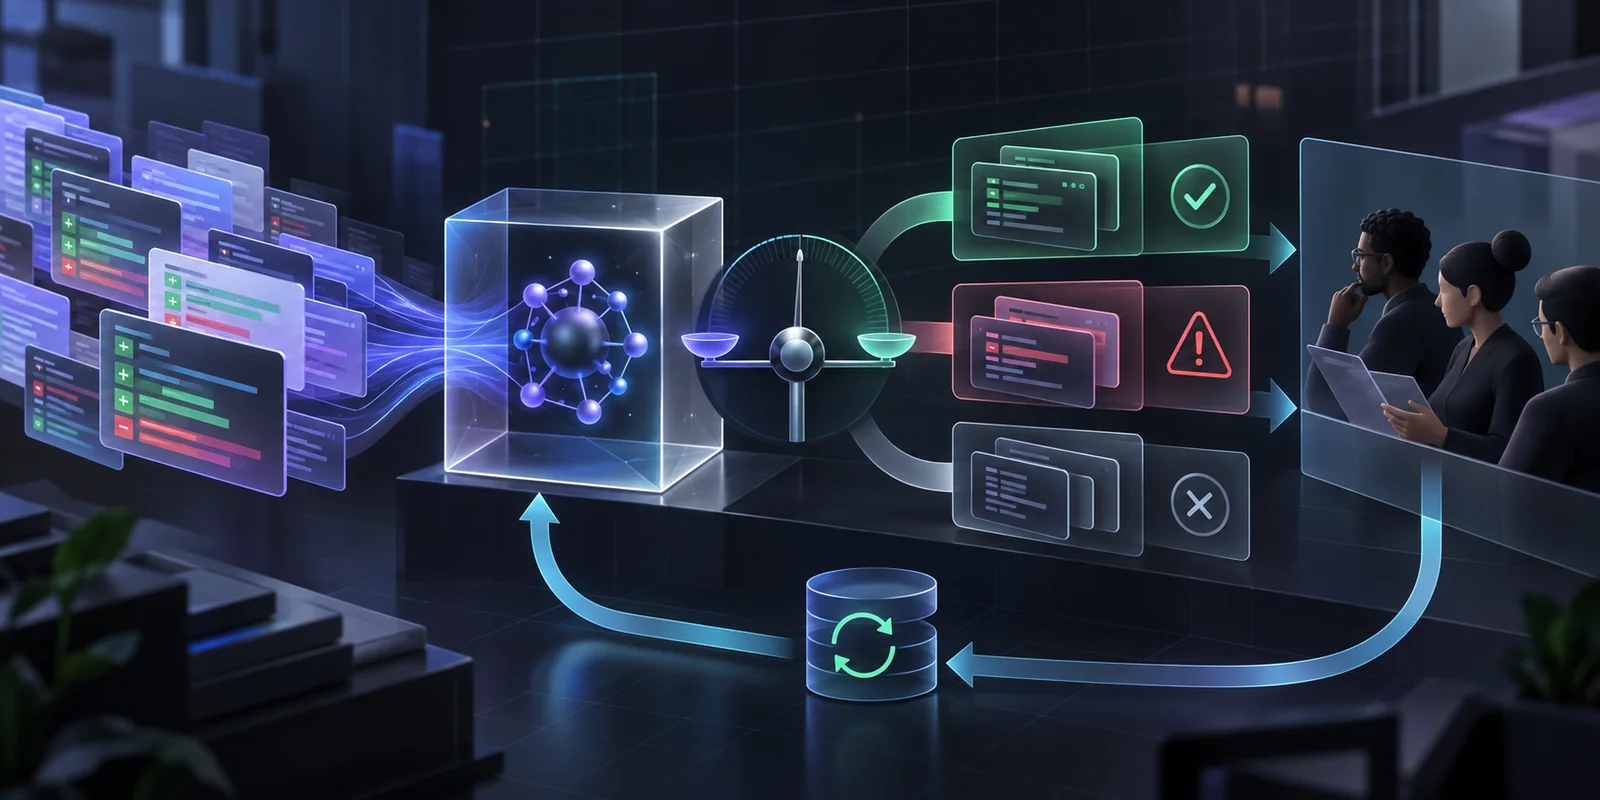
ReviewBench fixes the base and head commits for each PR at the state before later corrections. The agent receives that stable change and produces findings with a file, line range, and message. That atomic unit matters: one long review can contain a correct observation and three unverifiable claims. Scoring the entire comment would hide the mixture; separating findings makes it possible to identify what matched a known issue, what was noise, and what deserves fresh evaluation.
A semantic matcher then decides whether a candidate finding describes the same problem as one in the golden set, even if it uses different wording or points to nearby lines. Unmatched findings are not automatically discarded: they go through the same standard used to label the corpus. This avoids two common shortcuts: literal matching that misses valid equivalents, and a closed golden set that penalizes an agent precisely for discovering something new.
Chapter 03
Decision 1: represent your workload, not the most convenient distribution
The public corpus contains 219 PRs from 187 repositories across 19 languages. GitHub modeled language and repository size from 103.9 million pull requests, but made one deviation explicit: it weighted medium and large changes more heavily to avoid filling the benchmark with trivial one-file edits. That transparency is more valuable than pretending the sample is perfectly natural. A benchmark should document the population it represents and the deliberate bias it introduces to expose difficult work.
Your company also needs a private slice. Separate by language, criticality, change type, size, architecture, and context required. A reviewer that works on TypeScript refactors can fail on SQL migrations or mobile permissions. Keep a development set for prompt tuning and a holdout that the team does not use for iteration. If every holdout error is immediately turned into a prompt example, you stop measuring generalization and start memorizing the exam.
Chapter 04
Decision 2: build ground truth from sources that disagree
No reviewer knows every problem in a change. ReviewBench combines human comments, later author fixes, deterministic tools, and several model-based reviewers. It then deduplicates equivalent observations and judges each one under a common rubric. The source proposes candidates but does not determine truth: a linter can be wrong, a human can prioritize style, and a model can confidently state a false premise.
For an internal benchmark, define a true positive as an observation that is correct, verifiable, relevant, and actionable under the repository's real bar. Record severity, category, scope, and required context as well. Do not erase disagreements: a dispute between correctness and reliability can be informative even when both reviewers agree the problem exists. Preserve code evidence and the human decision, because the golden set is a reviewable version of team judgment, not immutable natural truth.
Chapter 05
Decision 3: calibrate and version the automated judge
The benchmark uses a Claude Sonnet 5-based classifier to label findings and a human process to audit it. GitHub reports 96.6% agreement on true positive versus false positive after independent review; that number describes agreement on this corpus, not universal accuracy or a replacement for engineers. The methodology itself documents much larger disagreements on exact severity and category, a reminder that structured output does not eliminate ambiguity.
Version the prompt, model, thresholds, matcher, corpus, and rubric as one configuration. When the judge changes, recompute affected labels and metrics, and retain a stratified human sample to detect drift. Include cases with mitigation outside the diff, duplicate comments, and plausible but harmful advice. If the same model generates the review and decides whether it was good, add independent review: shared blind spots can inflate an improvement without the system learning to review better.
Chapter 06
Decision 4: choose an operating point, not a magic score
Precision answers how much noise the agent introduces; recall answers how many known problems it recovers. A team using comments as suggestions may accept more coverage. An automated gate needs high precision, especially at critical severity, because repeated false positives stop delivery and erode trust. F1 merely gives both equal weight. Fβ makes another preference explicit, but no combination decides how much a miss costs compared with an unnecessary interruption.
Also read results by category and severity. The average can hide that the agent catches style and simple tests while missing security or concurrency. ReviewBench separates grounded metrics, comparable against the golden set, from augmented metrics that recognize new findings through the judge. Its methodology warns that augmented recall depends on the agent's own discoveries and should not be the sole cross-system ranking. Track duration, cost per PR, comment volume, and duplicate rate as well to observe the complete experience.
Chapter 07
Hypothetical example: evaluate before enabling a merge gate
Suppose a fintech has Kotlin services, a TypeScript frontend, and a Swift app. The team selects 120 historical PRs, freezes the commits before review, and builds findings from human comments, later fixes, static analysis, and related incidents. Senior engineers adjudicate a sample, document the action threshold, and reserve 30 PRs as a holdout. This example is hypothetical: it does not represent a Wasyra client or result.
It first runs the agent silently and calculates precision and recall by stack, category, and severity. If the average improves but Swift security false positives double, it does not promote globally: it adjusts retrieval and policies on the development set, runs the holdout once per serious candidate, and compares cost and latency too. It then enables non-blocking comments on a fraction of repositories and records whether authors fix, dismiss, mute, or duplicate the finding.
Only a narrow class of findings becomes a gate: for example, secrets confirmed by a deterministic tool and validated by policy. Everything else stays in suggestion mode while the team compares offline signal with online action. Rollback means being able to restore the previous agent and judge configuration, not merely turning off a model. That separation prevents a statistical improvement from becoming operational authority before proving it helps developers.
Chapter 08
Decision 5: require correspondence with production
GitHub says ReviewBench offline movements anticipated the direction of Copilot code review A/B experiments and publishes an example with changes in addressed rate, recall, volume, and cost. These are provider-reported results for its product, not a guaranteed effect for another agent. The transferable lesson is the validation design: define in advance which online signal corresponds to each offline metric and check direction, magnitude, segments, and side effects.
Do not turn addressed rate into automatic truth: an author can apply a wrong suggestion, ignore a correct one for lack of time, or accept a cosmetic change. Combine behavior with human sampling, escaped defects, time to resolution, reversions, and perceived noise. Set a stop condition if volume rises without improving critical findings or if a sensitive repository drifts. The benchmark reduces uncertainty before rollout; production decides whether the system deserves to remain.
Chapter 09
Limits that must be written down
ReviewBench is a research preview built from public projects. Its results may not represent private code, monorepos, internal rules, minority languages, or changes that require running infrastructure. The corpus deliberately reweights PR sizes, the golden set can be incomplete, and the judge can share assumptions with evaluated models. A leaderboard also changes when products, configurations, models, or the benchmark itself change. Record the exact date, version, and configuration for every comparison.
Do not confuse evaluation with permissions either. An agent that detects a bug well does not thereby earn the right to edit the branch, approve the PR, or block a release. Keep finding quality, execution authority, and evidence that a fix passed tests and review separate. That boundary preserves the benchmark's value without turning it into a security certification it never claimed to be.
Chapter 10
The decision is not to buy a score, but to build measurable trust
A useful code review benchmark needs five connected decisions: a representative corpus, plural ground truth, a calibrated and versioned judge, metrics aligned with the operating point, and online validation. ReviewBench provides an open reference for designing them and exposes its limits as well. Use it as a reproducible starting point, add your private workload, and require every improvement to preserve its evidence.
If your team is evaluating an engineering agent, the next step is not enabling the merge gate. It is defining which changes it represents, which finding deserves action, who audits the judge, and which production signal will confirm value. Wasyra can help turn that contract into a measurable pilot with gradual permissions and explicit rollback, without confusing a good demo with a system ready to operate.
FAQ
Frequently asked questions
Is a public benchmark enough to choose a code review agent?
No. It provides a reproducible comparison, but it must be complemented with representative private PRs, your own review bar, and online validation before granting operational authority.
Which metric matters more: precision or recall?
It depends on the operating point. An automated gate prioritizes precision to avoid blocking on noise; suggestion mode may accept lower precision for broader coverage. Results should always be segmented by severity and category.
Written by
Wasyra Engineering
Modernization, architecture, and reliable delivery
Wasyra Engineering documents patterns for moving legacy systems without freezing delivery or breaking ownership.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
Engineering
Ephemeral credentials for agents: what changes with GitHub Apps
Five gates for letting an agent operate on repositories with short-lived tokens, least privilege, safe transport, and verifiable recovery.
ArticleEngineering
GPT-6 prompt caching: how to measure cost and latency
GPT-6 adds prompt-caching diagnostics and controls. Five decisions for reducing repeated work without hiding costs, failures, or isolation.
ArticleKeep reading
Keep reading
Engineering
Ephemeral credentials for agents: what changes with GitHub Apps
Five gates for letting an agent operate on repositories with short-lived tokens, least privilege, safe transport, and verifiable recovery.
ArticleEngineering
GPT-6 prompt caching: how to measure cost and latency
GPT-6 adds prompt-caching diagnostics and controls. Five decisions for reducing repeated work without hiding costs, failures, or isolation.
ArticleEngineering
Hybrid physical AI: what inference should stay on the robot
Microsoft proposes offloading robot inference to edge or cloud. Six decisions for gaining capacity without handing safety to the network.
Article