Generative UI: how to evaluate AI-built interfaces
OpenAI's Intelligent UI shows a product shift: the model can choose among text, visuals, and interactive controls, and stream an interface while it answers. This guide turns that development into an engineering contract for teams that need utility without giving the model unrestricted control over the experience or its effects.
- Published
- min read
- 7 min read
- Categoría
- AI Systems
On this page
7 chapters- 01A contract for generative UI
- 02How can generative UI work without improvising the whole interface?
- 03Six gates for deciding what the model may generate
- 04Hypothetical example: a B2B proposal comparator
- 05State and actions: where the real risk appears
- 06How do you evaluate generated UI before production?
- 07Limits, rollout, and the implementation decision
Chapter 01
A contract for generative UI
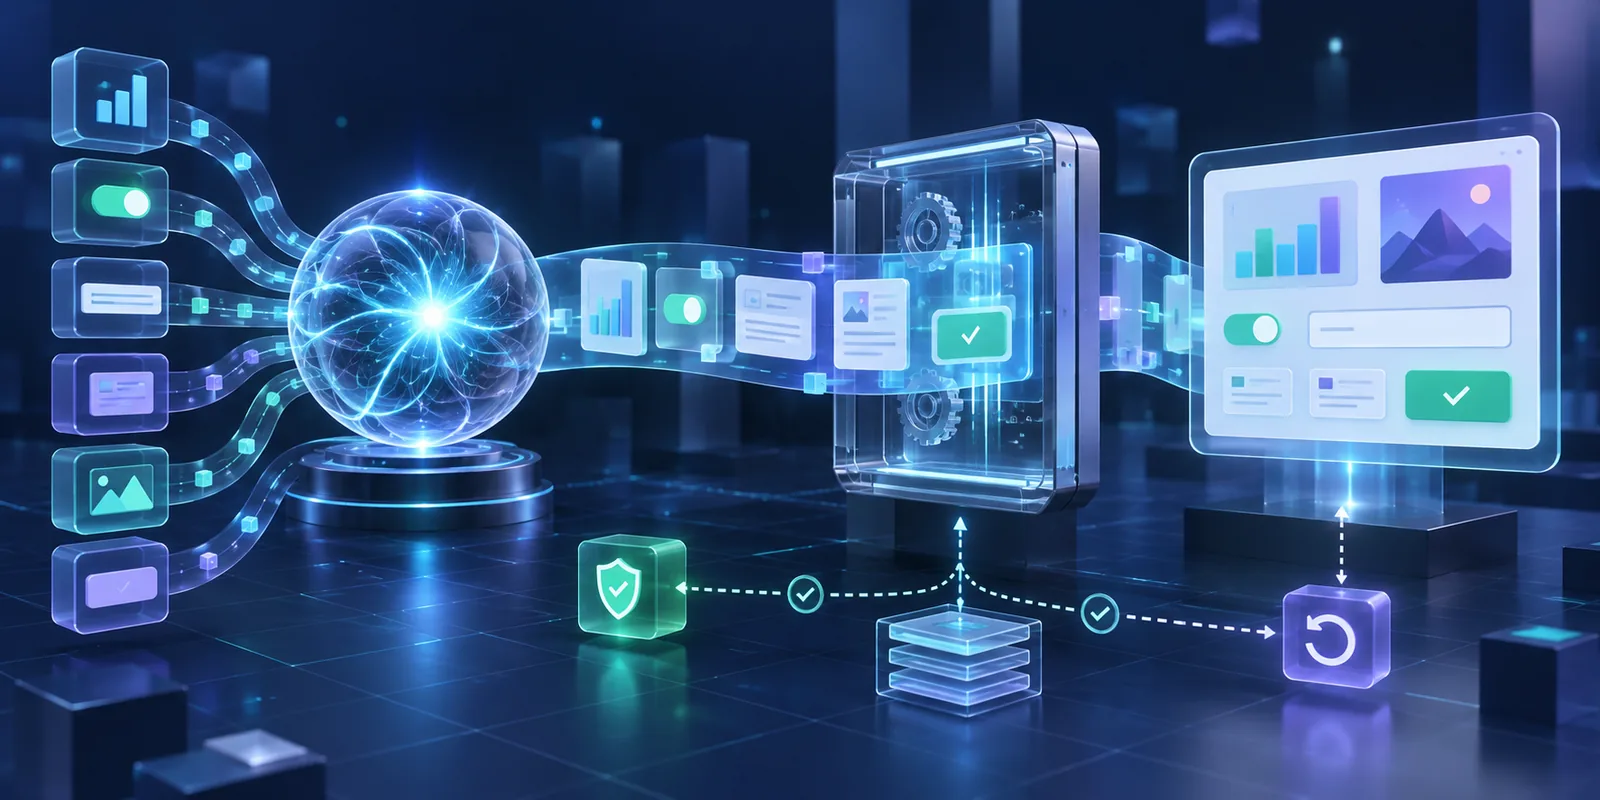
A generative interface is an experience where the model decides which combination of text, visuals, and controls best resolves an intent. It should not mean that the model writes and executes arbitrary frontend code. On October 7, 2026, OpenAI introduced Intelligent UI in ChatGPT: GPT-6 can compose responses with graphics, buttons, forms, and interactive experiences, using a library of native components and a compiler that processes the interface while the model generates it. For a product team, the right decision is not to copy the demonstration but to define six verifiable boundaries: when generated UI is appropriate, which components are allowed, which state is authoritative, which actions require confirmation, which accessibility conditions must hold, and which outcome proves usefulness. Without those gates, a visually convincing interface can hide incomplete data, lose state, trigger an unintended effect, or degrade on mobile and screen readers. With them, generation stays contained inside a design system, permission model, and observable test plan.
The central development is one calendar day old when this article is published. OpenAI also says the model's design judgment still needs improvement. Its speed and quality figures are provider-run internal evaluations; they are not benchmarks reproduced by Wasyra or evidence that generated interfaces work better for every product.
Chapter 02
How can generative UI work without improvising the whole interface?
The useful mechanism separates three decisions. First, the model interprets the task and selects a representation: text for a direct answer, a table for comparison, a chart for spotting a pattern, or controls for exploring alternatives. Second, it produces a structured specification inside a closed component vocabulary. Third, a runtime validates that specification, resolves data and state, and renders known elements. The model organizes; the host retains authority over code, capabilities, and effects.
OpenAI describes a library of native streamable components for Intelligent UI and a compiler that displays the interface progressively. That architecture avoids waiting for a complete answer, but it creates intermediate states: a component without data yet, a block that changes order, an action not yet enabled, or an answer that is still reasoning. Every state needs explicit semantics. A placeholder must not look like a confirmed total, and a control should not become active before its arguments and permissions are valid.
OpenAI's developer surfaces offer a related reference, not an exact description of the announced product. Its Apps SDK separates tool contracts, structured content, UI resources, and widget state; its UI library provides tokens and accessible components. That separation is transferable: verifiable data in one channel, presentation in another, and side effects behind tools with narrow contracts.
Chapter 03
Six gates for deciding what the model may generate
The contract should be evaluated before rendering and again before any effect. The following six gates cover the minimum boundary between a flexible response and a controlled application. Not all require human approval, but none should depend only on the model remembering a prompt instruction.
| Gate | Operational question | Passing evidence |
|---|---|---|
| 1. Intent | Does interaction improve the task over plain text? | The modality wins in a task test, not only in visual preference. |
| 2. Components | Does every element belong to an allowed library? | The schema rejects unknown types, props, and combinations. |
| 3. State | Which source wins after every interaction? | Reload, history revisit, and retry preserve coherent state. |
| 4. Effects | Which actions read, write, charge, or communicate? | Permission, preview, confirmation, and idempotency are verified per action. |
| 5. Accessibility | Does the task work with keyboard, zoom, and a screen reader? | Order, focus, names, contrast, and reflow pass automated and manual checks. |
| 6. Outcome | Does the UI help complete the task correctly? | Success, errors, abandonment, time, and recovery improve without hiding risk. |
Chapter 04
Hypothetical example: a B2B proposal comparator
Imagine a product leader who uploads three vendor proposals and asks which one best reduces delivery risk. The model could respond with an editable matrix: scope, dependencies, assumptions, milestones, and unsupported clauses. When the priority changes from speed to operational continuity, the matrix reorders criteria and explains why. That interaction adds more than a text block because it lets the user explore a multi-criteria decision without losing the traceability of each claim.
This example is hypothetical. A safe implementation would keep the original documents as immutable evidence, link every derived cell to a page or excerpt, and expose weights as visible user state. The model could propose a weighting, but not hide it. If data is missing, the UI would show unknown and allow a clarification request; it would not turn absence into zero. Exporting the analysis would be a read action. Sending a recommendation to the committee would be a separate action with recipients, preview, and confirmation.
The primary test would not ask whether the matrix looks modern. It would measure whether the decision-maker finds real contradictions, identifies uncertainty, corrects a weight, and recovers state after leaving and returning. A generated UI fails even if it is attractive when it accelerates the wrong conclusion.
Chapter 05
State and actions: where the real risk appears
In a conversation, at least four states can exist: tool data, component state, session memory, and the summary the model believes is current. If any can overwrite the others without a version or merge rule, carts revert to an earlier quantity, filters are ignored by the model, or confirmations show values different from those submitted. Define an authoritative source per field, include a version in every mutation, and make conflicts visible instead of silently resolving them.
Actions need an even stricter boundary. The component may emit intent, but the server must revalidate identity, permission, arguments, current state, and impact limit. A purchase, deletion, publication, or external message needs a stable summary of what will happen and a confirmation close to the effect. Idempotency prevents duplicates when the interface retries after a network problem. A receipt with an identifier distinguishes success, pending status, and uncertain outcome.
Test resumption as well. Close the view during streaming, return from history, repeat a tool after a timeout, and switch devices. Correct recovery is not drawing the same card again; it is reconstructing workflow truth without repeating the effect.
Chapter 06
How do you evaluate generated UI before production?
Build the evaluation set from real tasks and difficult states, not attractive prompts. Include an answer where text is enough, another that needs comparison, partial data, a slow tool, an irreversible action, a reopened session, and long content in both languages. For every case, define the expected modality, allowed components, required data, forbidden actions, and success criterion. This detects both over-generation and failure to provide useful interaction.
Measure in layers. For structure: schema validity, unknown components, and tree stability during streaming. For content: source fidelity, treatment of missing values, and correspondence between data and visuals. For interaction: correct completion, input errors, focus, and recovery. For effects: authorization, confirmation, idempotency, and auditability. For experience: time to useful content, cumulative layout changes, reflow at 200%, and complete keyboard and screen-reader navigation.
Compare against a fixed baseline: structured text or a manually designed UI. The experiment must use the same task and the same data. A higher click rate is not enough when errors or reversed actions increase. Promote generative UI only when it improves the target outcome within the latency, accessibility, and risk budget, and keep a fallback path for invalid specifications or unavailable capabilities.
Chapter 07
Limits, rollout, and the implementation decision
Not every response should become a mini application. Generated UI adds planning tokens or compute, validation, streaming states, combinatorial testing, and component maintenance. It can also create choice overload, variations that are hard to document, and surfaces users do not recognize across sessions. For regulated or high-frequency flows, a fixed interface often preserves muscle memory, auditability, and supportability better. Reserve generation for variable tasks where composition genuinely changes with context.
Start with read-only components and a narrow domain. Log the detected intent, generated specification, library version, fallbacks, and task outcome without retaining more personal data than necessary. Then enable reversible editing. External actions come last, one at a time, with their own permissions and receipts. A kill switch should disable a template, component, or action without removing the entire experience.
The executive decision is straightforward: adopt generative UI when task variability justifies dynamic composition and when you can prove all six gates. If the team cannot yet version state, contain effects, or test accessibility, the next step is not generating more UI; it is strengthening the runtime. Wasyra can help turn a concrete use case into a measurable slice with a component contract, evaluation plan, and reversible rollout, without confusing a visual demo with a production-ready system.
FAQ
Frequently asked questions
What is a generative interface?
It is an experience where a model selects and composes text, visuals, and controls for a task inside a library, schema, and permission model defined by the application.
Should the model generate arbitrary frontend code?
Not for a reliable production flow. It is safer to generate a validated specification that can use only components and actions allowed by the host.
What should be measured beyond visual quality?
Task success, accuracy, errors, state and recovery, time to useful content, accessibility, permissions, idempotency, and reversed effects.
Written by
Wasyra AI Systems
Trust, copilots, and enterprise adoption
Wasyra AI Systems covers guardrails, suggestion-first modes, and review design so work assistants earn real adoption.
Series
AI systems that actually reach production
A series on agents, copilots, and guardrails for bringing AI into real work without breaking trust or operations.
Posts in this seriesMore from this author
More from this author
AI Systems
Cybersecurity AI: how to govern access by tier
Six controls for enabling dual-use cyber capabilities with identity, isolation, limited egress, monitoring, and verifiable revocation.
ArticleAI Systems
Model extraction: how to protect your AI gateway
Six controls for detecting coordinated model extraction without blocking legitimate customers or turning every prompt into a false alarm.
ArticleKeep reading
Keep reading
AI Systems
Cybersecurity AI: how to govern access by tier
Six controls for enabling dual-use cyber capabilities with identity, isolation, limited egress, monitoring, and verifiable revocation.
ArticleAI Systems
Model extraction: how to protect your AI gateway
Six controls for detecting coordinated model extraction without blocking legitimate customers or turning every prompt into a false alarm.
ArticleAI Systems
Async agents: how to keep work moving without blocking
Five gates that let an agent advance while slow tools run without losing dependencies, control, state, or evidence.
Article